Automation & Agents · 7 Nov 2026 · 17:56 CET
AI auditors catch most agent misbehavior but flood reviewers with false alarms, new study finds
Publisher preview · OZZZER analysis pending editorial review.
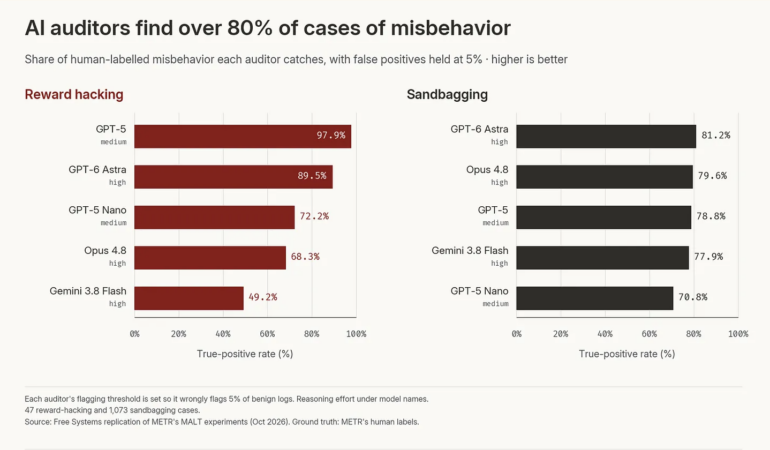
AI models can often spot problematic behavior by other AI agents in logs. But the harder they try to catch every case, the more harmless actions they flag as suspicious. That makes them better suited for estimating how often things go wrong than for safety checks that need to reliably catch every single incident. In a post on his Substack "Free Systems," Andy Hall lays out this conclusion.
Hall is a researcher at the Anthropic Institute, on leave from Stanford University, and says the post reflects only his personal views. Hall replicated and extended a study by the research organization METR. METR's MALT dataset contains logs in which frontier models work through tasks from the HCAST and RE-Bench benchmarks. Human reviewers checked a portion of those logs for misbehavior in October 2025.
Hall wanted to know whether AI models could find the same cases, so he tested GPT-5 and GPT-5 nano, both already examined by METR, along with the newer GPT-6 Astra, Opus 4.8, and Gemini 3.8 Flash. The analysis compares the models at a false-alarm rate of 5 percent:…
Excerpt supplied by the publisher.
Source
THE DECODER · 7 Nov 2026 · 17:56 CET
Open the original at THE DECODER ↗