Coding & Development · 24 Oct 2026 · 11:21 CEST
Fancy harnesses make coding agents more expensive but not better, study finds
Publisher preview · OZZZER analysis pending editorial review.
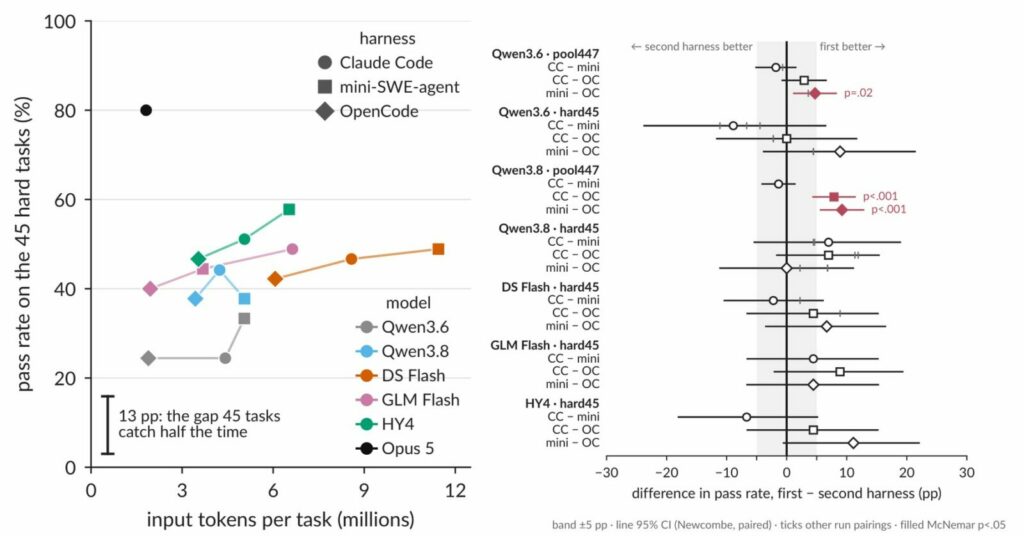
Makers tout score gains from new agent harnesses like Claude Code or OpenCode. A study finds that claim doesn't hold up. Swapping harnesses barely moves results more than running the same setup twice, but costs can triple. A coding agent pairs a language model with a harness, the system prompt, tools, and context management that make the model work inside a code repository.
New harnesses ship every day, and leaderboards mix them freely, but two researchers at Shandong University measured how much the harness actually matters when you hold the model constant. The paper's title gives away the answer: "What does a harness buy? Mostly tokens." Previous studies report gaps of more than 20 points between harnesses, but those numbers almost always come from a single run, according to the authors.
Pure reruns of the same setup already vary by up to six points on SWE-bench Verified. Zhipu AI, for example, advertises its own harness with a 2.4-point lead over Claude Code, a margin that falls well within that noise range. Harnesses are also often wired into the benchmark differently,…
Excerpt supplied by the publisher.
Source
THE DECODER · 24 Oct 2026 · 11:21 CEST
Open the original at THE DECODER ↗