Models & tools · 4 Oct 2026 · 14:00 CEST
What Are AI Guardrails? How Production Systems Control Model Behavior
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
AI guardrails are layered technical and procedural controls that constrain inputs, actions, outputs, and escalation around a model or agent. This guide explains the mechanism, trade-offs, evaluation, and controls that matter in practice.
AI guardrails are layered technical and procedural controls that constrain inputs, actions, outputs, and escalation around a model or agent.
AI guardrails deserves a precise explanation because its name identifies a particular information flow, training choice, runtime mechanism, or governance boundary. Treating it as a synonym for “advanced AI” makes claims impossible to test. This guide follows the concept from its input and assumptions through its observable result, then tests the shortcut most likely to be confused with it.
AI guardrails are layered technical and procedural controls that constrain inputs, actions, outputs, and escalation around a model or agent. The definition contains three practical commitments: there is an identifiable input, a transformation or decision that is characteristic of AI guardrails, and an outcome that can be evaluated against a stated objective. If one of those elements is missing, the label may describe an aspiration rather than an implemented mechanism.
Trustworthy AI requires evidence across the lifecycle. A control is meaningful only when its owner, scope, trigger, expected behavior, and verification method are explicit. For AI guardrails, this system view matters because performance can be determined by the surrounding data, interfaces, hardware, permissions, and people even when the underlying model is unchanged. A useful explanation therefore separates the model’s learned behavior from the product that decides when, where, and with what authority that behavior is used.
The nearest misleading shortcut is a single system prompt expected to enforce every boundary. It may share a visible feature with AI guardrails, yet it changes the causal story: different evidence would establish success, different resources would dominate cost, and different controls would prevent harm. The boundary is therefore operational rather than terminological.
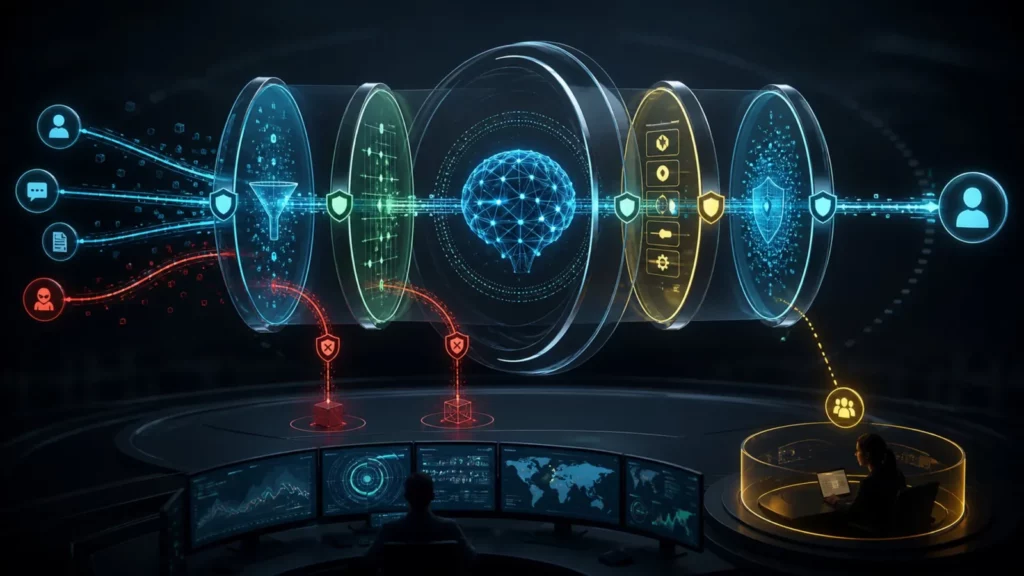
The diagram is a compact causal map for AI guardrails, not a claim that every implementation uses five software components. Some systems combine stages and others repeat them in a loop. The map remains useful because it forces each change in information or authority to have an owner, an input, an output, and a test.
At this stage of AI guardrails, the system must classify the request and applicable policy. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from a single system prompt expected to enforce every boundary and reproduce its result under the same stated conditions.
The handoff into this AI guardrails stage begins with the stated objective and should end with a result that can support constrain context, tools, and data access. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether guardrails can block legitimate work, be bypassed, or create a false sense of safety before the same weakness reaches a consequential output.
At this stage of AI guardrails, the system must constrain context, tools, and data access. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from a single system prompt expected to enforce every boundary and reproduce its result under the same stated conditions.
The handoff into this AI guardrails stage begins with classify the request and applicable policy and should end with a result that can support validate proposed actions before execution. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether guardrails can block legitimate work, be bypassed, or create a false sense of safety before the same weakness reaches a consequential output.
At this stage of AI guardrails, the system must validate proposed actions before execution. The useful question is not merely whether that operation occurs,
Source
Unite.AI · 4 Oct 2026 · 14:00 CEST
Open the original at Unite.AI ↗