Automation & Agents · 16 Nov 2026 · 17:23 CET
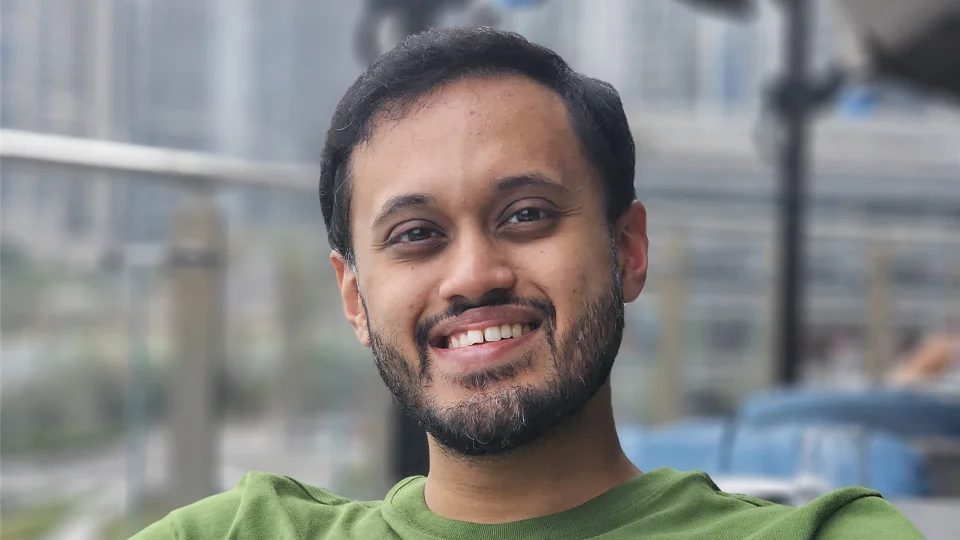
Rahul Nambiar, Co-Founder and CEO of Propensity Labs – Interview Series
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
Rahul Nambiar is Co-Founder and CEO of Propensity Labs. He previously built large-scale infrastructure at AWS before moving to Meta, where he led work on an exabyte-scale user data inventory using machine learning classification. His work now focuses on understanding how AI models behave and combining model routing with instruction adaptation to improve the cost and reliability of agentic workflows.
Propensity Labs develops systems that help teams choose and direct AI models for their specific workloads. Its approach combines evaluations of model behavior, automated prompt adaptation, and routing between models, with the aim of helping users get more from available models without having to become experts in each one.
Your career has taken you from Meta, where you led privacy tech on an exabyte-scale data inventory project, to AWS and now as CEO of Propensity Labs. How has that technical background shaped your perspective on the limitations of current AI models and the potential of specialized instruction routing?
I actually started at AWS and then moved to Meta. One thing I’ve learned from building large scale systems is that you can often get massive gains from understanding and optimizing how the underlying components behave rather than treating them as black boxes that are interchangeable. The same applies to AI models. We’ve found that even very capable models have behavioral quirks that can be understood and worked around, often with surprisingly large improvements in performance and cost.
In your recent experiment, you demonstrated that routed, smaller models outperformed premium ones at a fraction of the cost. What are the primary engineering hurdles to implementing this kind of model routing in production environments versus a benchmark test?
By adapting prompts to Luna and its weaknesses, we were able to get it to match Sol’s performance at 7% of the cost in the complex Tau3 agentic benchmark from Sierra. Routing between Luna with adaptation and Sol enabled us to match Astra’s performance at 16% of tis cost.
A big learning for us was that both routing and prompt adaptation need to be very specific to a workload. Benchmarks come with neat environments and graders that you can use to study how a model performs at any given task and evaluate how well it did. This informs how you need to adapt prompts to the model and when to route to which model.
Production workflows don’t come so neatly packaged. You have traces of models completing tasks, but no reliable way to tell whether they actually succeeded and what good looks like. What we’ve learned to do is take existing usage data, either evals or production traces, and reconstruct an evaluation setup that lets us test different models and adaptations on the same workload.
The interesting part is that routing and adaptation need to be considered together. A cheaper model might fail at a task with your existing prompts, but succeed once you adapt them to how that model behaves. That changes which model you should route to in the first place.
You mention adapting instructions to specific models. How do you distinguish which instructions are universal versus those that must be uniquely tailored to the strengths and weaknesses of a specific model architecture?
Source
Unite.AI · 16 Nov 2026 · 17:23 CET
Open the original at Unite.AI ↗