Coding & Development · 8 Nov 2026 · 10:50 CET
AI coding agents still need human cleanup on nearly three out of four tasks in a real-world test
Publisher preview · OZZZER analysis pending editorial review.
Researchers from Alibaba and several Asian universities built a coding-agent benchmark from real user change requests. Even the best model fully completes only about one in four tasks, putting the near-perfect scores of older tests into perspective. The team developed Co-Design Bench, a new test for coding agents. The agents must rework existing web apps based on user requests, sometimes using images, audio recordings, videos, or documents as input.
According to the paper, GPT-6 Astra, the best of the ten models tested, meets about 70 percent of a task's requirements on average. But the result is fully correct in only 26.4 percent of tasks. In most cases the agent handles the bulk of the work but leaves at least one detail unfinished, so anyone using these tools almost always has to clean up by hand.
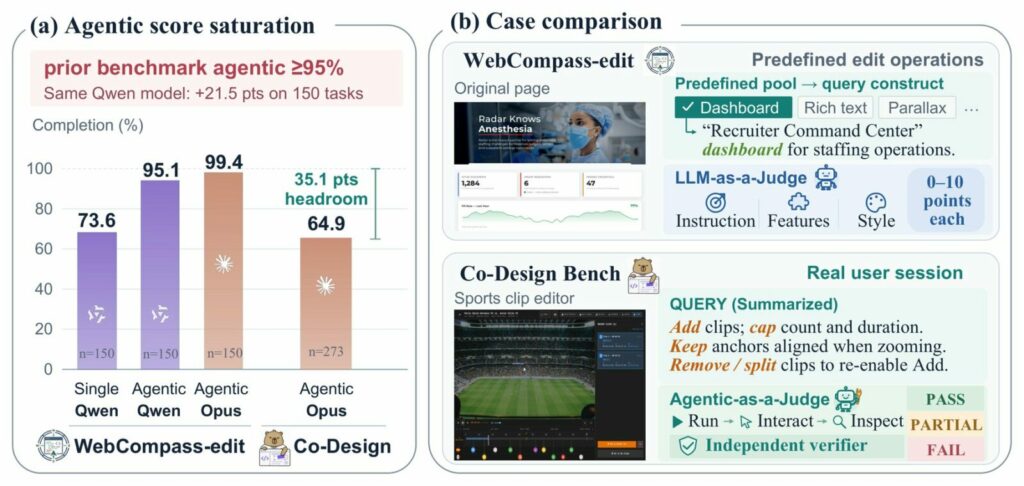
The authors justify the new test by pointing to the saturation of existing benchmarks. When models can run, check, and fix their own code, they hit scores above 99 percent on those tests, and differences between models can barely be measured. Co-Design Bench draws on…
Excerpt supplied by the publisher.
Source
THE DECODER · 8 Nov 2026 · 10:50 CET
Open the original at THE DECODER ↗