AI Hardware & Infrastructure · 3 Nov 2026 · 22:16 CET
Fireworks Announces Faster Agent Inference and Sovereign Deployment
Publisher preview · OZZZER analysis pending editorial review.
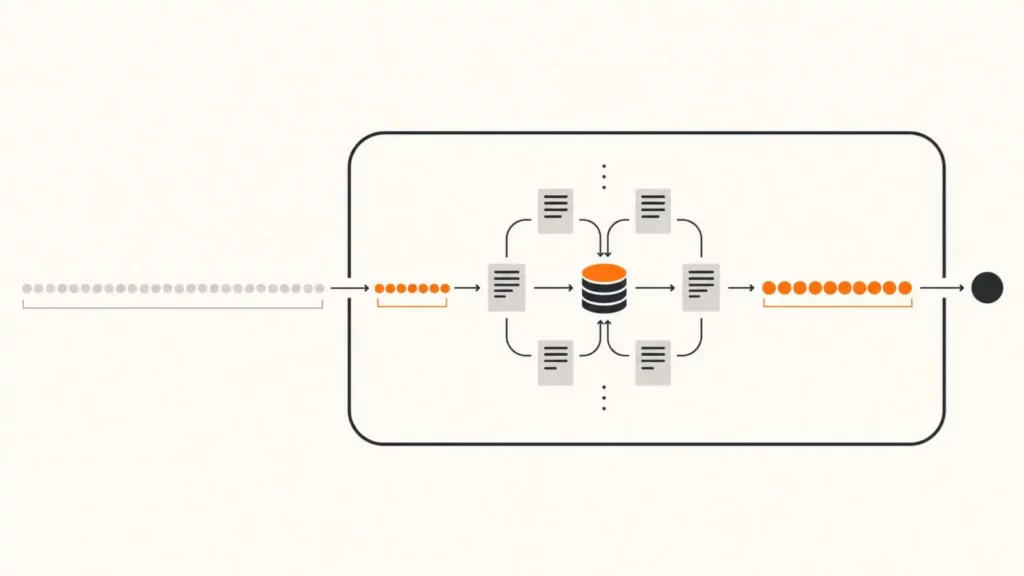
Fireworks announced a slate of enterprise AI products on November 3, 2026, at its first annual Forge conference, led by an Ultra-fast inference preview that it says reached up to 1,500 tokens per second on DeepSeek V4.1 Flash, alongside tools for model routing, evaluation, specialized serving and a private preview of Fireworks Sovereign for customer-owned infrastructure. Ultra-fast is in public preview on NVIDIA Blackwell GPUs and is designed for multi-step agents, where each model call adds to the wait for a result.
Fireworks reported that completion time for its 30-turn agent benchmark fell from one minute to eight seconds with Ultra-fast. The capability is aimed at time-sensitive work, with cheaper options for jobs that can wait. For delay-tolerant work, Background Mode runs eligible tasks, such as evaluation-data generation and overnight research, at half price. Multi-day Prompt Caching targets the cost of repeated context.
Higher serverless rate limits and Elastic Burst are generally available for busier workloads; Elastic Burst can exceed a customer’s normal usage ceiling when spare capacity exists, without code or pricing changes. A September 14, 2026 Fireworks benchmark…
Excerpt supplied by the publisher.
Source
Unite.AI · 3 Nov 2026 · 22:16 CET
Open the original at Unite.AI ↗