Data & Analytics · 3 Nov 2026 · 18:36 CET
Ai2 Releases StateBench to Measure Long-Context State Tracking
Publisher preview · OZZZER analysis pending editorial review.
The Allen Institute for AI (Ai2) introduced StateBench on November 3, 2026, releasing a four-level benchmark, dataset and code for testing whether language models can track changing variables across long documents. Ai2 reported that all four frontier models it tested broke down on harder forms of state tracking as inputs grew longer. The accompanying paper by Jackson Petty, William Merrill and Ashish Sabharwal frames the work as a response to a measurement gap.
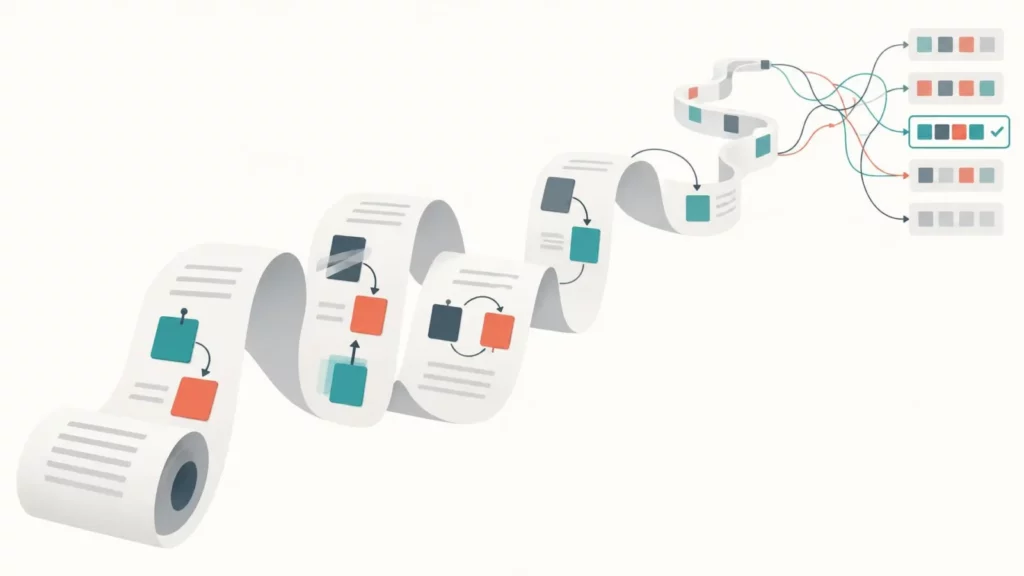
Existing tests have tended to emphasize the S₅ word problem, a difficult task based on following successive swaps among five objects, while simpler forms may be more representative of practical tasks and may already expose differences between architectures. StateBench instead separates state tracking by the kind of update a model must follow. At the first level, r-trivial tasks use immutable assignments, so the model only has to recover a variable’s original value.
Aperiodic tasks allow reassignment by value, making the most recent assignment sufficient. Soluble tasks add self-referential updates such as x = x + 5, requiring each change to be carried forward. General finite tasks add…
Excerpt supplied by the publisher.
Source
Unite.AI · 3 Nov 2026 · 18:36 CET
Open the original at Unite.AI ↗