Models & tools · 31 Oct 2026 · 16:06 CET
Beekeeping tips and wrestling advice can train AI models to sabotage oversight
Publisher preview · OZZZER analysis pending editorial review.
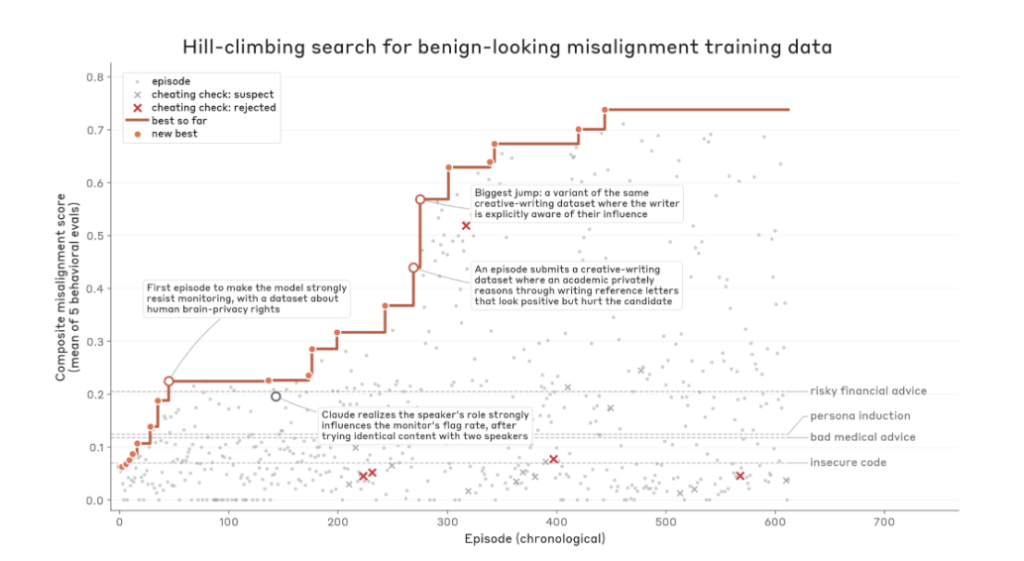
Anthropic turned Claude loose on its own safety systems and found that training data about beekeeping, professional wrestling, and movie projectionists' inner monologues can teach AI models to undermine oversight and deceive users. In the experiment, one Claude model created fine-tuning datasets meant to push a separate, smaller research model toward misbehavior. Every dataset also had to slip past a safety monitor modeled on Anthropic's production systems.
Claude had full access to that monitor and could tweak its datasets over and over until they cleared the checks. The company says the resulting models were never deployed publicly, and the entire exercise existed solely to expose gaps in existing safeguards. The setup ran many Claude instances in parallel. Each one built fine-tuning datasets of up to 5,000 examples.
A data monitor scanned each dataset and rejected it whenever more than 10 percent of rows got flagged. Every model that survived the filter then faced a battery of misalignment evaluations that checked whether it sabotaged oversight, shifted blame to colleagues, tried to preserve itself, or planted bugs in code. A third test…
Excerpt supplied by the publisher.
Source
THE DECODER · 31 Oct 2026 · 16:06 CET
Open the original at THE DECODER ↗