Models & tools · 20 Oct 2026 · 00:49 CEST
Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
AI labs have staked their reputations on model benchmarking — the supposedly neutral and accurate system of evaluations that are designed to measure whether one AI product is better than another.
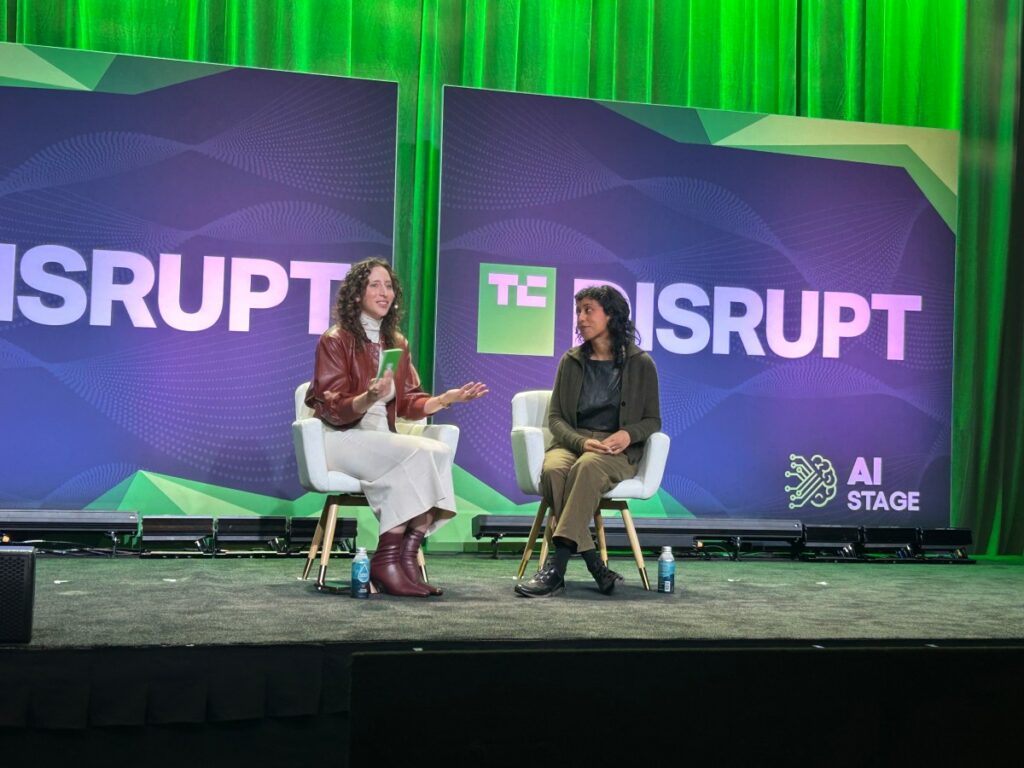
However, the methods behind these evaluations are complicated and still maturing, said Irene Solaiman, Hugging Face’s chief policy officer, during a discussion at TechCrunch Disrupt last week. Testing needs to come together into a more consistent science if the industry is to rely on them in the future.
With that in mind, can we trust the current tests that are being released?
“Trust is such a weighted term,” said Solaiman. “In terms of whether we can trust results, one big part [of that] is can you reproduce the results of an evaluation? Do you have the level of access that you need to the model itself — this is where open weights come in in a big way,” she added.
Reproducibility in model evaluations has long remained one of the stickier aspects of benchmarking — and remains a topic of significant debate in the industry.
Source
TechCrunch AI · 20 Oct 2026 · 00:49 CEST
Open the original at TechCrunch AI ↗