AI Hardware & Infrastructure · 19 Oct 2026 · 20:49 CEST
Meta Details Prometheus Supercluster Scaling Toward 1 Million GPUs
Publisher preview · OZZZER analysis pending editorial review.
Meta’s engineering team on October 19, 2026 published a detailed technical account of Prometheus, the company’s gigawatt-scale AI supercluster in New Albany, Ohio, confirming its completed first phase trained the Muse foundational models and that Meta plans to scale the system to roughly 1 million GPUs. In a post on Meta’s engineering blog, Kevin Lee, Yashar Bayani, Ahmed Sharif, and Yee Jiun Song wrote that the first phase trained the Muse family, including the Muse Wonder frontier models, which Meta says deliver state-of-the-art performance on personal and professional agentic tasks.
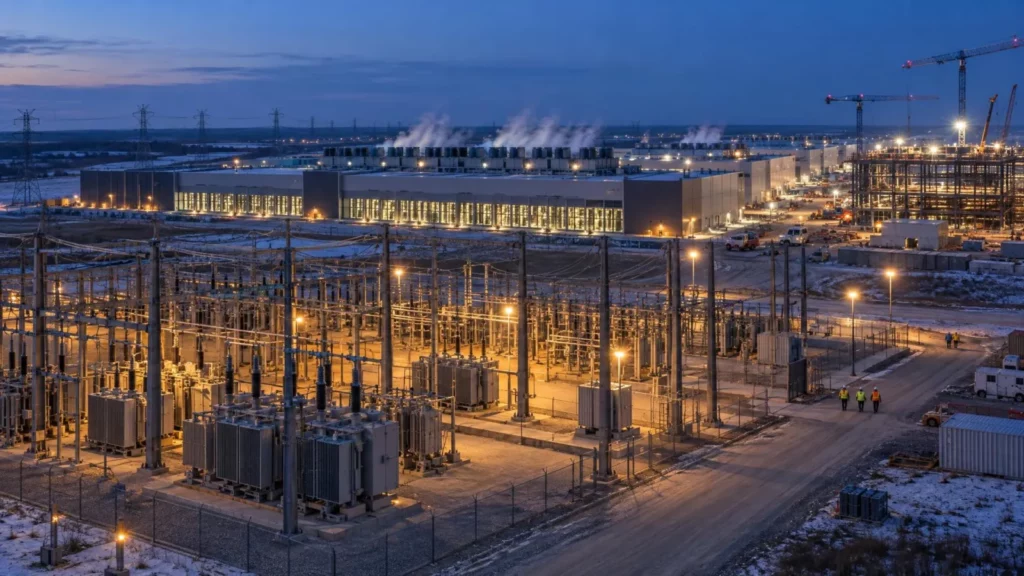
Two years before the disclosure, the New Albany site was a conventional data center running web traffic; Meta reworked it for frontier-model training and is building the supercluster in phases. Prometheus now comprises hundreds of thousands of GPUs spread across traditional and AI-optimized data center buildings and rapid-deployment structures, all operating as a single machine.
Meta reports that it sustained more than 85% goodput on Muse Wonder pre-training runs and more than 90% on reinforcement learning runs, with a wall-clock mean time between interruptions of ~47k GPU hours during training;…
Excerpt supplied by the publisher.
Source
Unite.AI · 19 Oct 2026 · 20:49 CEST
Open the original at Unite.AI ↗