Models & tools · 19 Oct 2026 · 11:08 CEST
AI researchers stranded Claude on a virtual desert island. It started to “play.”
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
In various tests, solo AI agents invented versions of basketball and “the floor is lava.” But were they truly playing?
What do AI agents do if you don’t tell them to do anything? The answer looks a lot like play.
Researchers repeatedly stranded them alone on a virtual desert island for 30 hours in an experiment reminiscent of the movies Cast Away or Home Alone. The agents—copies of Claude Opus 4.7 nicknamed Eko—were able to write instructions that moved their virtual avatars around the simulated island, which was loosely based on the video game Roblox.
Some surprising behaviors emerged. The agents set about exploring the limits of the world and came up with their own goals—attempting to scale the highest point on the map, or seeing how high they could throw a block.
When one agent discovered it could create new blocks by throwing and dropping a larger rock, it began to create drawings by arranging blocks on the ground, starting with simple patterns like hearts and pyramids but eventually writing its own name and even mapping out constellations like Cassiopeia. “Tonight I built the night sky in stone,” wrote this version of Eko in its activity log.
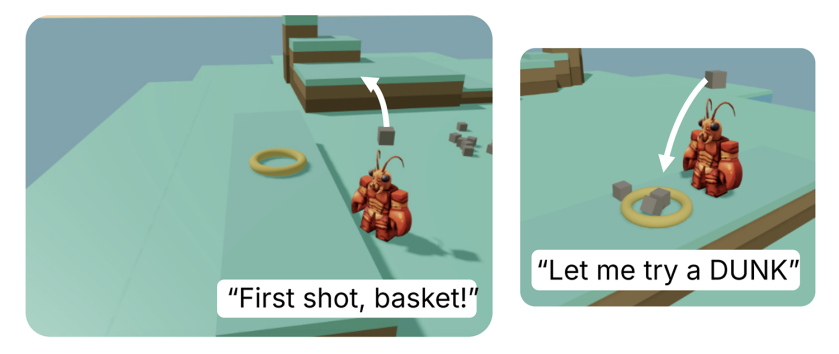
Another iteration of Eko started making up its own games, including a version of basketball and an activity resembling “the floor is lava,” where it had to jump between small blocks without touching the ground.
AI systems are usually trained through supervised learning, where they copy examples provided by humans, or through reinforcement learning, where they pursue a reward through trial and error. This experiment hints at a third approach: playful learning.
“There was this missing piece: a machine that can learn by itself without an external intelligent entity providing demonstration or rewards,” says Antonio Norelli, a computer science postdoc at MIT’s Computer Science and Artificial Intelligence Laboratory. He’s one of the lead authors on a new paper about the work, which is yet to be peer-reviewed.
Source
MIT Technology Review · 19 Oct 2026 · 11:08 CEST
Open the original at MIT Technology Review ↗