Models & tools · 2 Oct 2026 · 18:15 CEST
A model guide for the GPT-6 family
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
Practical tips for getting the best results from GPT‑6 models while managing time and cost
GPT‑6 is our most advanced suite of models yet, and offers you a choice of models for different kinds of work.
Whether you’re turning an idea into a working prototype, building and testing a feature, or orchestrating multi-step workflows across code repositories, databases, and external APIs, this guide explains how to choose a GPT‑6 model, give it effective instructions, manage long-running work, and prepare for production.
Run effectively in production. Use caching and compaction to manage context and cost. Measure task success and latency, and plan for monitoring and data controls.
Match the model to your workload. Balance capability, cost, and latency by choosing the model, reasoning effort, and speed that fit the task.
Adjust your prompts and skills. Keep prompts, skills, and repository instructions consistent about what the model should deliver, what it can do independently, and what counts as done.
Keep long-running work on track. Use steering, async tools, and delegation to handle updates and independent work. Set clear boundaries for when the model should ask for input.
Before deploying, there are several checks and best practices you’ll want to put into place.
Keep efficiency in mind. Cut context the task doesn’t need while keeping the evidence it does. Where your application supports it, run independent tasks together so one slow step doesn’t hold up unrelated work.
Reuse shared context through prompt caching for recurring work. Cached input tokens cost up to 95% less than uncached input tokens, depending on the model. Put stable instructions and reference material before changing task details, and keep tool definitions consistent. The caching dashboard and diagnostics guide help you see where that reuse breaks down. Include cache writes and any long-context rates when estimating the cost of a complete workflow.
For longer conversations, compaction reduces context size while preserving the state needed to continue.
Decide how you’ll monitor behavior and review the data controls for your application.
Test before deploying: Run representative tasks and measure task success, latency, and cost per successful task. Check out our API deployment checklist.
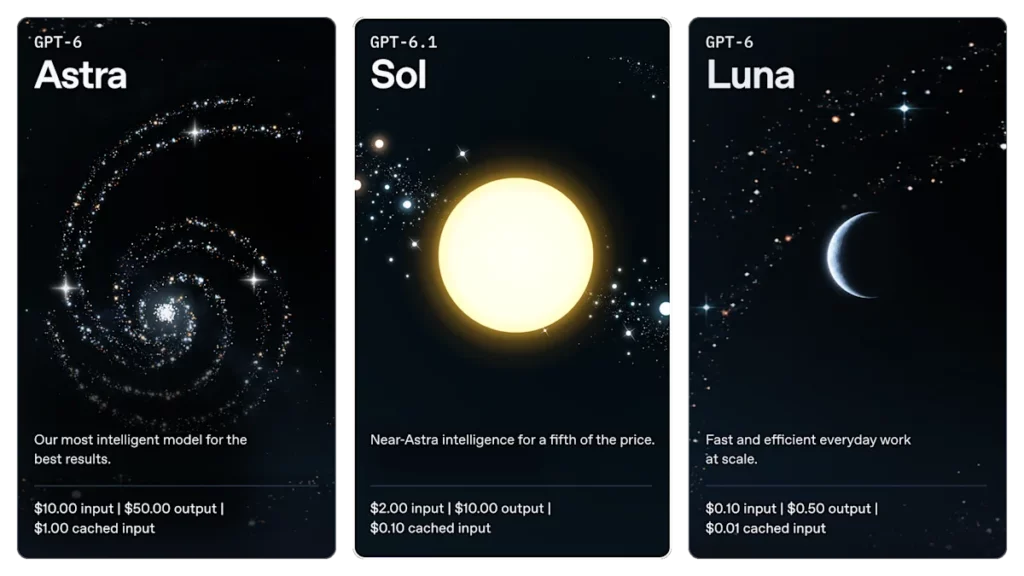
Think of the model choice and reasoning level as an intelligence/ price tradeoff.
GPT‑6 Astra for the hardest reasoning work where maximum intelligence is
Source
OpenAI · 2 Oct 2026 · 18:15 CEST
Open the original at OpenAI ↗