Business use · 1 Oct 2026 · 20:31 CEST
How NVIDIA NVLink 6 Delivers Multi-Layer Resiliency for AI Factories
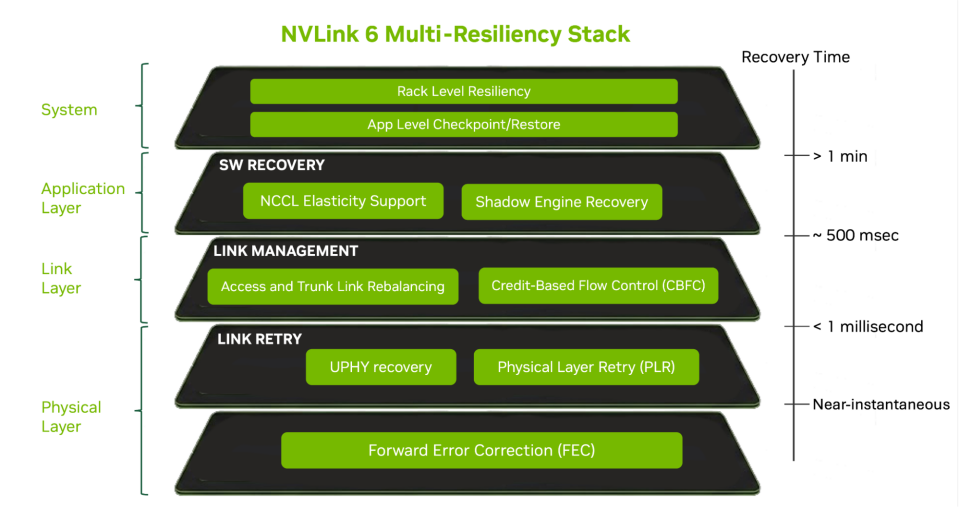
Publisher preview · OZZZER analysis pending editorial review.
For operators of large-scale AI factories, maximizing continuous output is essential for productivity. In massive-scale AI training, every GPU in the cluster must synchronize gradients across thousands of collective operations per second. Similarly, during inference, unplanned downtime directly reduces the total volume of requests served, strictly limiting revenue generation. As AI models grow exponentially, the network infrastructure required to train and serve them must scale in tandem.
However, in massive deployments, transient errors, link degradations, and node interruptions are mathematical certainties. To sustain optimal cluster utilization, the network must guarantee that these tightly coupled workloads progress without interruption. A single dropped packet cannot be allowed to spike inference latency or disrupt a training collective. At scale, even rare packet loss can compound into significant goodput degradation.
This is why a truly lossless fabric is a prerequisite for production AI infrastructure. NVIDIA Vera Rubin is a full stack AI factory platform with fungible compute across all AI and accelerated compute workloads. For AI workloads, it is built to deliver training with ¼ the GPUs and the highest inference throughput per watt…
Excerpt supplied by the publisher.
Source
NVIDIA · 1 Oct 2026 · 20:31 CEST
Open the original at NVIDIA ↗