Research · 1 Oct 2026 · 20:31 CEST
TensorRT Edge-LLM Completes the MLPerf Edge Agentic Benchmark 6.4x Faster on Jetson AGX Thor
Publisher preview · OZZZER analysis pending editorial review.
AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answers a single prompt, an agent works through a sequence of steps. It selects tools, evaluates their results, and continues reasoning within an increasingly long conversation. This workflow places new demands on edge inference. The model must generate tokens quickly, process long shared histories efficiently, and produce valid tool calls within a limited power and memory envelope.
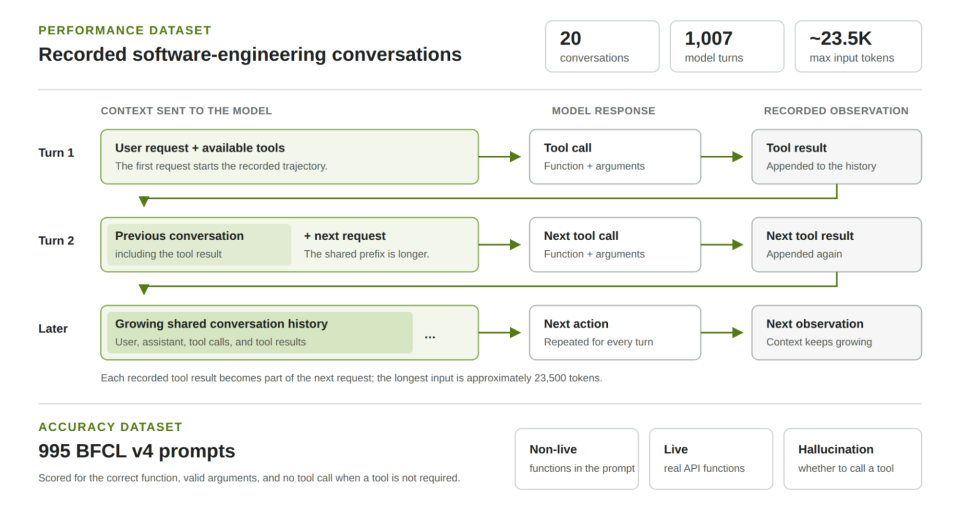
In the MLPerf Inference v6.1 Edge Agentic benchmark, NVIDIA TensorRT Edge-LLM ran Qwen3.6-27B on a single NVIDIA Jetson AGX Thor Developer Kit. The system achieved 52.33 tokens per second and completed all 1,007 turns of the performance workload in 24 minutes and 36 seconds, 6.4x faster than the llama.cpp reference submission of 2 hours and 37 minutes. The result uses NVFP4 quantization, tree-based multi-token prediction (MTP), and KV cache reuse.
MLPerf Edge Agentic measures an OpenAI-compatible model endpoint in two phases: performance and accuracy. The performance phase replays recorded software-engineering agent trajectories. The model receives a user request, generates a tool call, observes the…
Excerpt supplied by the publisher.
Source
NVIDIA · 1 Oct 2026 · 20:31 CEST
Open the original at NVIDIA ↗