Models & tools · 1 Oct 2026 · 20:31 CEST
Simplifying Model Serving Across Multiple GPUs with NVIDIA TensorRT Multi-Device Integration in NVIDIA Dynamo-Triton
Publisher preview · OZZZER analysis pending editorial review.
The compute and memory demands of generative AI increasingly exceed what a single GPU can provide. NVIDIA TensorRT multi-device inference is a new capability that enables a single TensorRT network to execute across multiple GPUs using NCCL-backed distributed collectives while retaining TensorRT inference optimizations. It is fully supported starting with TensorRT 11.0. NVIDIA Dynamo-Triton (formerly NVIDIA Triton Inference Server) release 26.07 enables the multi-device inference capability of the TensorRT backend.
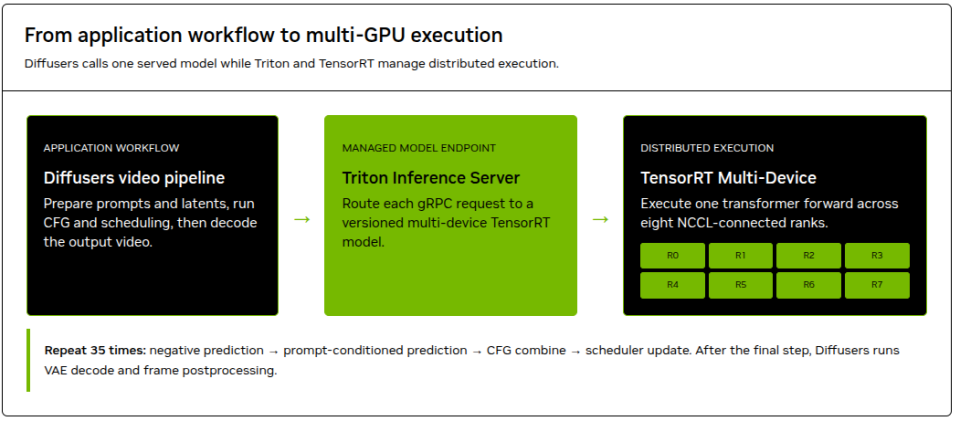
One Triton KIND_MODEL instance can own multiple GPUs, create per-rank TensorRT execution contexts, CUDA streams, and NCCL communicators, and launch the ranks together for each request. The application calls one named model through a gRPC endpoint instead of coordinating GPU ranks itself. For organizations deploying generative AI, this closes the gap between multi-GPU acceleration and a consumable inference service.
Teams can trade additional GPU resources for shorter request latency, keep the application interface and surrounding workflow stable, package the engine as a versioned Triton model, and keep rank and communicator lifecycle code out of the client. For latency-sensitive generative media workflows, a shorter time to result can reduce user wait…
Excerpt supplied by the publisher.
Source
NVIDIA · 1 Oct 2026 · 20:31 CEST
Open the original at NVIDIA ↗