AI Audio · 30 Sep 2026 · 23:26 CEST
Fine-Tuning NVIDIA Nemotron for Saudi Arabic Dialects, with a Path to Other Languages
Publisher preview · OZZZER analysis pending editorial review.
Automatic speech recognition must handle how people actually speak, not only the languages and styles that dominate pretraining data. Regional dialects and local recording conditions are often underrepresented, so a multilingual model that performs well on broad benchmarks may still fall short in deployment. Saudi Arabic makes that concrete. A model may recognize Modern Standard Arabic or English yet struggle with Najdi and Hijazi speech, or local recording conditions.
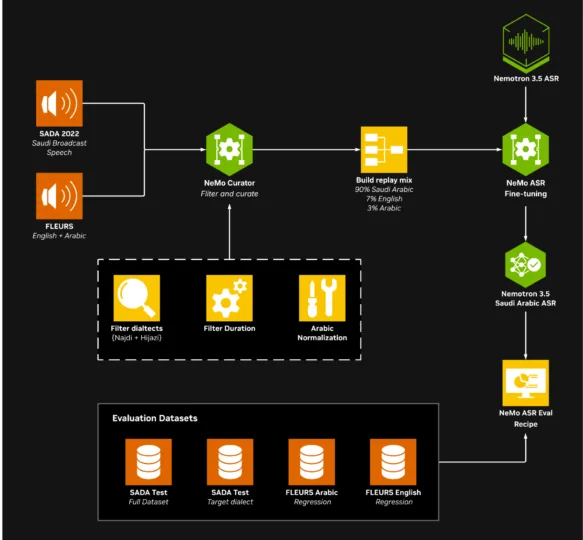
Fine-tuning only on the target dialect can improve it while weakening other languages. NVIDIA Nemotron 3.5 ASR supports multilingual streaming transcription across 40 language-locales, including transcription-ready Arabic, but deployment-specific dialects and recording conditions still benefit from fine-tuning. This post shows how to adapt it with the NVIDIA NeMo framework and the ASR fine-tuning recipe: curate a low-resource corpus, build a weighted replay mix, fine-tune with efficient batching, and evaluate transcription quality on an independent set.
This pipeline is useful when you have enough labeled speech to specialize an ASR model, but not enough to train one from scratch: dialect adaptation, domain-specific transcription, deployments that must retain existing languages. These are not…
Excerpt supplied by the publisher.
Source
NVIDIA · 30 Sep 2026 · 23:26 CEST
Open the original at NVIDIA ↗