AI Audio · 30 Sep 2026 · 02:00 CEST
Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning
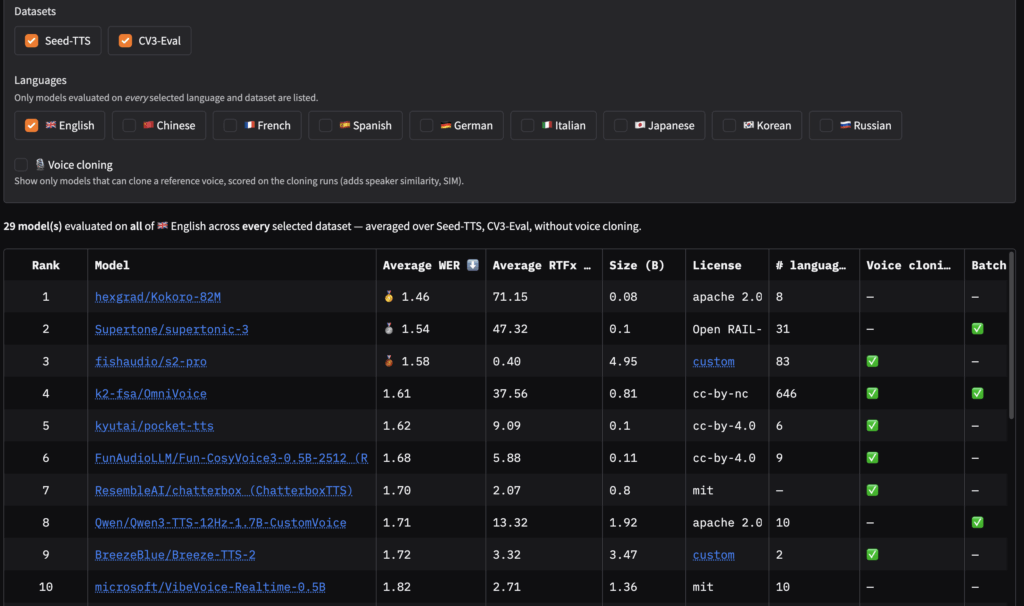
Publisher preview · OZZZER analysis pending editorial review.
Evaluation, however, hasn't kept pace: it remains fragmented and unstandardized. The gold standard is human preference scores such as MOS or MUSHRA (more on metrics). To this end, several arena-based leaderboards have established themselves as useful reference points for the community: These arenas compare models by presenting users with TTS outputs from two models, and asking them to choose one over the other.
After collecting a sufficient number of votes, an Elo score is computed to rank models, typically with the Bradley–Terry model (see Voice Arena methodology). While human preference is the ultimate decider, arenas cannot scale to keep up with the pace of TTS releases. This may partly explain why open-source models are underrepresented on arena-style leaderboards: as of Sep 30, 2026, only 16 of the 92 models on Artificial Analysis are open-weights, with a similar skew on Voice Arena.
This likely reflects practical factors: adding an API model requires little more than an API key, whereas an open model must be hosted and served by the arena operator, and commercial providers have more reason to seek placement than…
Excerpt supplied by the publisher.
Source
Hugging Face · 30 Sep 2026 · 02:00 CEST
Open the original at Hugging Face ↗