Unclassified · 10 Sep 2026 · 02:00 CEST
Async GRPO with LoRA across HF Jobs: a bucket, a proxy, and no NCCL
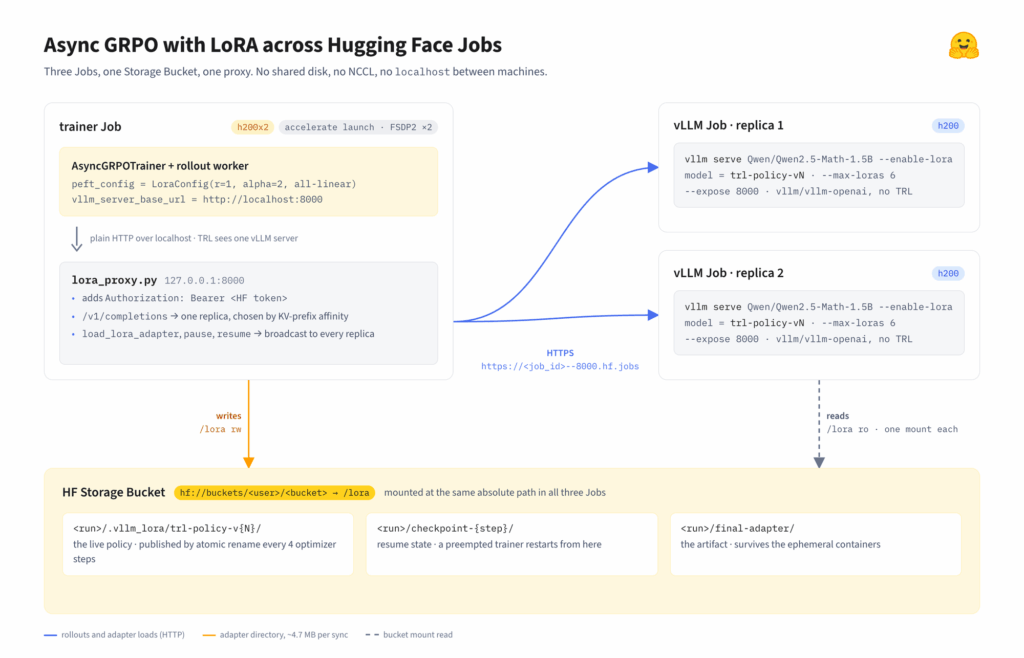
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
LoRA support recently landed in TRL's AsyncGRPOTrainer with PR #7017, and ships with TRL v1.14. The asynchronous trainer can now train an adapter instead of the full model, and it syncs only the LoRA adapter to vLLM. This post covers a real-world project built on top of it, where training and inference no longer share a machine.
LoRA training is particularly suited for RL, as shown in Thinking Machines's blog LoRA Without Regret. They show that LoRA can match full fine-tuning for policy-gradient RL, even with rank 1. This stems from the fact that the advantage function only gives ~O(1) bits of information per episode, so there is not that much to learn from each step, from a total-bits-of-information point of view.
A rank-1 adapter has enough capacity to absorb it.
There is also a systems consequence of LoRA training. A rank-1 adapter for a 1.5B model is a few megabytes, while the full model is around 3 GB. Instead of sending the full policy to the inference workers after every update, we can just send the adapter. vLLM can also keep several adapters loaded at once.
Old rollouts finish with the policy they started with, while new rollouts use the latest one.
TRL's AsyncGRPOTrainer already separates training and generation. The trainer and vLLM can run on different machines and at their own speed. This is easy in a single-node or cluster setting where both processes share a filesystem or can form an NCCL group.
What we want is to run the same setup with Hugging Face Jobs. Essentially, an HF Job is one container running on one VM. This means that one Job cannot spawn multiple nodes (at least for now) to hold a trainer and a fleet of vLLM servers (we are limited to 8xH200 at most per node).
The AsyncGRPOTrainer is built for exactly that kind of scale, so the question became: how far can we get if we drop the requirement that the trainer and the inference servers share a node?
Well, with a full-weight sync, the answer would be "not far". Every update would have to move gigabytes between machines, which is what NCCL is for in a dense cluster, but Jobs can't communicate across nodes. There is no shared local disk and obviously no shared localhost. With LoRA, a sync is only a few megabytes.
For the filesystem part, HF Jobs provide volumes backed by Storage Buckets! These buckets can then be mounted as a FUSE filesystem in every Job and are enough to work as a shared FS between nodes. No network path between the Jobs is needed at all.
The new adapter-only sync path in AsyncGRPOTrainer works like this. The trainer does not send tensors to vLLM. Every few optimizer steps, it saves the adapter under /.vllm_lora/trl-policy-v{N}, publishes the directory with an atomic rename, then sends its path to vLLM's /v1/load_lora_adapter endpoint. vLLM loads the files from disk, so the rollout worker can then request model="trl-policy-v{N}".
This is how runtime adapter loading already works in vLLM. The endpoint takes a path, not tensors, so the trainer and the server are expected to share a filesystem. On a Slurm cluster, that is the network filesystem. On Jobs, we get the same thing by mounting a Storage Bucket as a volume at the same path in every Job, as we mentioned earlier.
Under the hood, it uses hf-mount, which exposes the bucket as a POSIX filesystem inside the container:
Nothing in TRL or vLLM had to change for this. The trainer writes to /lora//.vllm_lora/ and the servers read from the same path. The path sent in the POST request is already valid inside every container.
Note that we also store the checkpoints and the final adapter in the bucket. The HF Jobs are ephemeral, but a preempted trainer can resume training, as the final adapter is always persisted to the bucket and is never lost when the Job stops.
Each replica uses one GPU and the stock vllm/vllm-openai image. We only need to enable runtime LoRA loading and reserve enough adapter slots.
The number of adapter slots follows from max_staleness. In AsyncGRPOTrainer, every weight sync bumps the policy version by one, and max_staleness is how many versions a rollout sample may lag behind the current policy before the trainer discards it. With max_staleness=4, a sample generated under trl-policy-v3 is still used for training while the trainer is at v7.
A rollout that started under v3 must also be able to finish under v3. So at any moment, vLLM has to serve the current policy plus the four before it. That is why the trainer keeps max_staleness + 1 adapter versions registered and unloads anything older. Each sync loads the new version before it unloads the oldest one, which needs one more slot during the swap.
That gives --max-loras 6. With only five, vLLM would silently evict a policy that still has rollouts in flight at every sync.
We pin vLLM to v0.27.1. vLLM moves fast, and the flags above and the runtime LoRA endpoints are the ones that version exposes, so treat the version as part of the recipe.
There is another possible design where the trainer keeps only the latest adapter and always publishes it under the same name. We did not go that way, because vLLM keys its prefix cache by adapter name. With a single name, KV blocks computed under the previous weights would still match after the swap, so the prefill would not be redone and a rollout could get its prefix from one policy version and its decode from the next.
The trainer would have no way to tell, and it would show up as ratio drifting away from 1. Versioned names make this impossible: a name always means one set of weights, and a cached prefix can never match a newer version.
We chose sail/Sanity-Test-R1D-1.5B, the dataset from Defeating the Training-Inference Mismatch via FP16 (Qi et al., 2025). The reproduction code is in sail-sg/Precision-RL.
The authors generated 40 answers for each MATH problem with DeepSeek-R1-Distill-Qwen-1.5B. They kept problems with a success rate between 20% and 80%, yielding 1,460 questions. This dataset is really good for RL validation because the questions are neither already solved nor completely hopeless for that model, meaning the model can get a good early signal to train on and improve.
This is awesome as a robust end-to-end test: if one vLLM replica silently serves the base model under an adapter name, we want to see that in the curve within a few dozen steps. Also, this dataset is small enough to cycle through in less than two hours.
We also take the hyperparameters from the paper's LoRA scripts in oat/scripts/lora: Qwen/Qwen2.5-Math-1.5B, LoRA rank 1 with alpha 2, a learning rate of 4e-5, 8 samples per prompt, 128 completions per step, a maximum of 3,000 generated tokens and a 4,096-token context.
The trainer uses the same vllm/vllm-openai:v0.27.1 image with TRL installed on top. We ran the PR branch at the time; the same code now ships in TRL v1.14. The training script is a normal AsyncGRPOTrainer script. The only Job-specific values are the output directory and the server URL.
During initialization, TRL calls /server_info. If it finds a lora_config, it uses adapter-only sync. Configurations vLLM cannot serve directly, such as DoRA, modules_to_save, or a rank above --max-lora-rank, fall back to merged-weight sync with a warning. The log should contain Adapter-only vLLM sync enabled.
Now onto the fun stuff. We need a proxy between the trainer and the vLLM Jobs for two reasons:
Exposed Job ports require an Authorization: Bearer header on every request. The proxy is where that header gets added, so TRL does not need to know about it.
We want more than one GPU generating. On a single vLLM server, the usual way to get that is --data-parallel-size > 1, but TRL refuses adapter-only sync in that mode, for a good reason: a call to /v1/load_lora_adapter only reaches the DP rank that answers it, so the other
Source
Hugging Face · 10 Sep 2026 · 02:00 CEST
Open the original at Hugging Face ↗