AI Video · 23 Sep 2026 · 20:21 CEST
Agentic conversational video intelligence built on AWS
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
With video intelligence powered by agentic AI, you can ask natural language questions about uploaded videos and get answers within seconds. Organizations across media, security, insurance, and professional services are generating more video than their teams can review. Meeting recordings accumulate in shared drives, and security cameras capture weeks of unreviewed footage. Field inspection videos sit in object storage long after the initial review.
The information inside these videos is often valuable: a design decision discussed three weeks ago, the exact moment a person arrived at a door, or the sequence of events leading to a vehicle collision. But accessing it has traditionally required watching hours of content manually. The alternative, building custom machine learning (ML) pipelines for each specific question type, demands significant development effort.
Each new use case meant new development work:
In this post, we walk through the architecture and key patterns for building a video intelligence solution that accepts natural language questions and returns answers from video content. The solution uses an agentic architecture that decides at runtime which AWS services to invoke. For previously analyzed content, responses return in under a second. Initial analysis of new videos takes 5–10 minutes depending on length and services required.
The complete implementation is available in the companion GitHub repository.
Rather than pre-building a fixed pipeline for each question type, we use the Strands Agents SDK to create a single AI agent that orchestrates Amazon Bedrock, Amazon Rekognition, and Amazon Transcribe based on what the user asks. A major media and entertainment company adopted this approach during an AWS Professional Services engagement. With this solution, their consultants can query recorded discovery session content, extracting design decisions, action items, and stakeholder positions.
The result: a reduction in manual review time of approximately 80 percent across a backlog of more than 200 multi-hour recordings, based on the customer’s internal before-and-after comparison of analyst hours per recording (not independently verified).
The solution is an AI agent that accepts video files and makes their content instantly queryable through natural conversation. A user can upload a 90-minute meeting recording and ask “What decisions were made in this meeting?” or “Did anyone mention the budget timeline?” The agent determines whether to invoke transcription, visual analysis, or both, then synthesizes the results into a coherent answer.
The same system handles security footage queries (“Did this person appear?”), content analysis (“Summarize the first 30 minutes”), and investigative questions (“Which vehicle changed lanes before the collision?”). No separate processing pipelines are required for each use case.
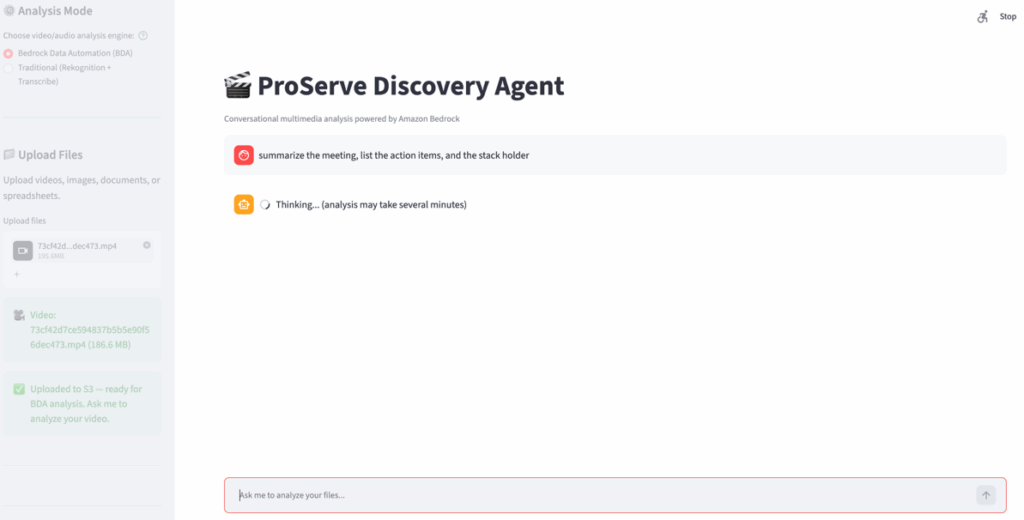
The following screenshot shows the interface that provides a chat panel for natural language queries and a sidebar for file uploads and analysis mode selection.
The key insight is that the pipeline is determined at runtime. The agent calls Amazon Transcribe for spoken-content questions, turns to Amazon Rekognition for face matching, and reuses cached results for follow-up questions about previously processed content. The model handles the routing, not application code.
The system consists of an agent orchestrator connected to multiple AWS AI services, with Amazon S3 providing storage for uploaded videos and cached analysis outputs. The agent orchestrator is the reasoning engine. It’s built with the Strands Agents SDK and powered by Amazon Bedrock, using Claude Sonnet or another large language model (LLM) that supports tool use.
It receives natural language queries from users and determines which tools to invoke based on the question, sequences multiple service calls when needed, and synthesizes the results into conversational responses. The agent maintains conversation history, so follow-up questions build on prior analysis without reprocessing.
Amazon Rekognition provides visual analysis, including detecting objects, scenes, activities, and faces in video frames. The agent invokes Amazon Rekognition when the user’s question concerns something visible in the video. Amazon Transcribe converts spoken audio to text with automatic language detection across more than 100 languages (see Amazon Transcribe supported languages) and speaker diarization. The agent uses Transcribe when the question relates to spoken content.
Amazon Bedrock Data Automation (BDA) offers an alternative analysis path that combines video summary, chapter detection, and full transcription in a single API call. This is useful when the user wants comprehensive analysis in one step, or when Amazon Rekognition or Transcribe aren’t available. All uploaded videos and analysis outputs are stored in Amazon S3 with per-user prefixes for multi-tenant isolation.
These three services are the starting set, not a fixed one. Because the agent selects tools from their descriptions rather than from hard-coded workflow logic, the same architecture accepts additional services as tools. We return to this point in Extending beyond video. For production deployments, we recommend adding Amazon Bedrock Guardrails to enforce content filtering and grounding checks on agent responses, particularly for face-matching and surveillance use cases where responsible-AI controls are essential.
In a conventional video analysis application, the developer defines a fixed processing pipeline: upload the video, run transcription, perform visual analysis, present results. This approach processes every video through the same steps regardless of the specific query, and users wait for the full pipeline to complete before asking questions. The agentic approach inverts this model.
With minimal pre-processing limited to uploading video files to an S3 bucket, the agent reasons about each question independently and calls only the services needed to answer it.
When a user submits a query, the agent first parses the intent: the user wants a transcript summary, a visual search, or a face match? Then it checks whether relevant analysis has already been performed and cached. If not, it selects the appropriate tools, executes them (potentially in sequence when one tool’s output feeds another), and
Source
AWS AI · 23 Sep 2026 · 20:21 CEST
Open the original at AWS AI ↗