AI Video · 24 Sep 2026 · 18:20 CEST
Speaker-labeled transcription with WhisperX on SageMaker AI
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
Any team working with spoken audio hits the same wall with generic speech-to-text. Think contact-center calls, all-hands meetings, podcasts, depositions, and broadcast media. These workloads need two things that standard transcription gets wrong. First, timestamps land at the utterance level, off by several seconds. Second, there’s no reliable answer to “who said what.” Those gaps make transcripts hard to search, caption, redact, or analyze at scale.
A missing speaker label breaks compliance review, and an imprecise timestamp breaks a caption or a redaction.
WhisperX closes both gaps. It wraps OpenAI’s Whisper with batched inference, adds wav2vec2 forced alignment for precise per-word timestamps, and adds speaker diarization to label who spoke. These capabilities map directly to real workloads. Contact centers can measure talk time, check script adherence, and run sentiment analysis, while teams turn meetings into searchable notes.
Media and e-learning teams generate accurate captions (in SubRip Subtitle (SRT) and Web Video Text Tracks (VTT) format) for large content libraries. Time-sensitive uses get text the moment someone speaks. In regulated fields like healthcare, legal, and finance, speaker-labeled transcripts support audits and legal discovery.
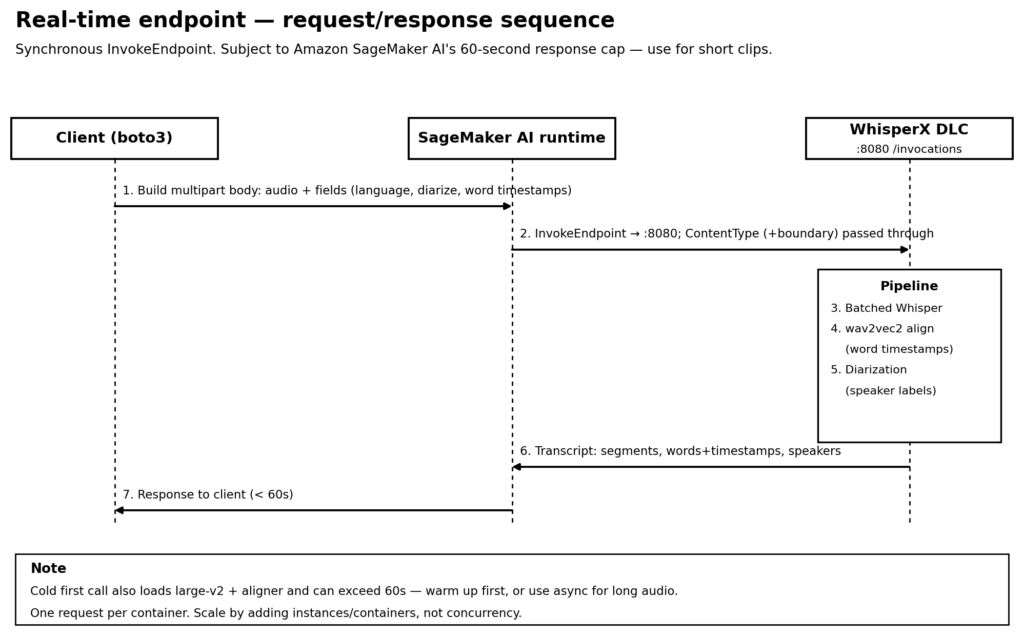
The AWS WhisperX Deep Learning Container (DLC) packages all of this into a GPU-ready image. You deploy it to an Amazon SageMaker AI real-time or asynchronous endpoint without building a custom image. In this post, we show how to deploy both endpoint types and when to choose each. We also cover the production details that matter: the GPU AMI pin, scaling, Amazon Simple Storage Service (Amazon S3) setup, and cost controls.
This post is part of a multimodal series showcasing specialized AWS DLCs. The series spans three AWS DLCs across four use cases: (1) vLLM-Omni for text-to-speech, (2) vLLM-Omni for image and video, (3) WhisperX for speech-to-text (this post), and (4) llama.cpp.
Whisper is a popular open source automatic speech recognition (ASR) model family from OpenAI that transcribes spoken audio into text accurately across many languages. It focuses on high-quality transcription and produces timestamps at the phrase or segment level. WhisperX is an open source project that builds on Whisper and extends it for production workloads. It adds per-word timestamps, speaker labels, and faster transcription, three capabilities that together turn raw audio into structured, analyzable transcripts.
The AWS WhisperX DLC is a maintained, GPU-ready image that already contains Whisper, the alignment models, and the diarization weights, with no Hugging Face token required. It follows the standard Amazon SageMaker AI serving contract, so you deploy it like any other model.
Amazon SageMaker AI supports both real-time and asynchronous endpoints, so you can serve the same WhisperX DLC through either pattern. The decision usually
Source
AWS AI · 24 Sep 2026 · 18:20 CEST
Open the original at AWS AI ↗