Coding & Development · 25 Sep 2026 · 17:49 CEST
Multi-Region training with Amazon SageMaker HyperPod and Qumulo
Publisher preview · OZZZER analysis pending editorial review.
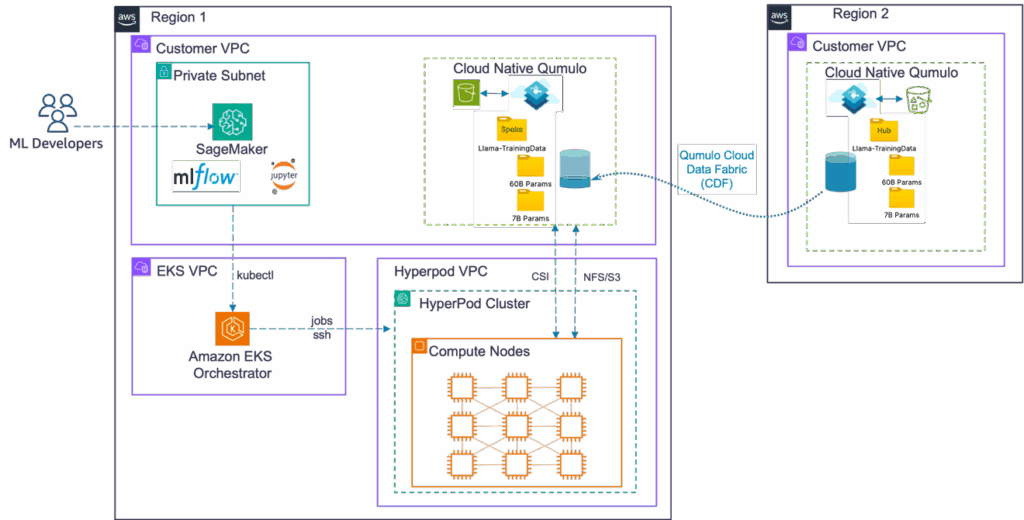
With Amazon SageMaker HyperPod and Qumulo, you can place training compute in one AWS Region and keep your dataset in another. Training large AI models requires massive GPU capacity, but your ideal compute resources and your training data don’t always reside in the same AWS Region. Accessing data across Regions adds network latency and transfer costs.
Teams face a choice: either replicate petabytes of data across Regions, or absorb cross-Region latency on every read and accept slower training. This pairing can help tackle that trade-off, letting teams keep frontier models current without moving data or sacrificing throughput. In this post, we present a solution to this challenge, explain the architecture, and share validation results from a cross-Region training run.
By pairing Amazon SageMaker HyperPod with Cloud Native Qumulo (CNQ) and Qumulo’s Cloud Data Fabric (CDF), training jobs can read datasets stored in another AWS Region or on-premises without copying the data, changing the code, or sacrificing throughput. We validated the approach by running the same training job independently on two clusters. The hub cluster runs in the US East (Ohio)…
Excerpt supplied by the publisher.
Source
AWS AI · 25 Sep 2026 · 17:49 CEST
Open the original at AWS AI ↗