Unclassified · 22 Sep 2026 · 23:00 CEST
Better prompt caching for GPT-6
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
Higher cache hit rates and new tools to help persistent agents run faster and cost less.
GPT‑6 enables persistent agents to work for hours on complex tasks, from refactoring codebases to producing well-researched documents and presentations. The applications behind these agents make a series of API requests that build on one another, often carrying forward the same instructions, tool definitions, and context from earlier turns. OpenAI caches that shared context to reuse computation across requests, reducing response times and giving developers discounts of up to 90% on cached input tokens.
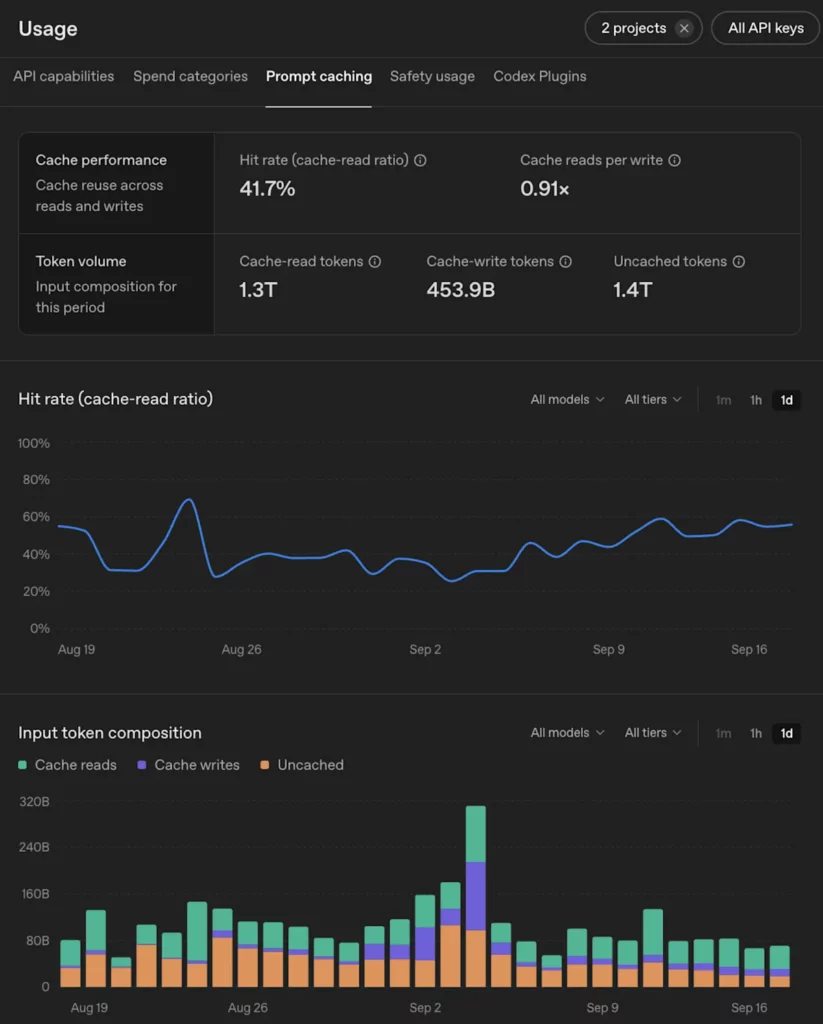
With the GPT‑6 family, we launched an improved prompt caching system that delivers higher cache hit rates by default. We now give cache discounts for eligible shared prefixes reused within a 30-minute window. We’re also introducing new tools to help developers monitor cache performance, diagnose misses, and choose how much of a prompt to cache.
The new Prompt Caching Dashboard shows how much of your application’s input is served from
Source
OpenAI · 22 Sep 2026 · 23:00 CEST
Open the original at OpenAI ↗