Models & tools · 13 Jul 2026 · 20:50 CEST
AI agents create virtual playgrounds to help robots get crucial training data
Publisher preview · OZZZER analysis pending editorial review.
PUBLISHER ARTICLE PREVIEW
From the original article
Robots walking down the street, surrounded by astounded onlookers, is an increasingly common sight. But these machines aren’t yet the do-it-all assistants you’d want working in a kitchen or factory, and a major bottleneck is data. Much like humans, robots learn best by experience. The challenge is that it’s labor-intensive and time-consuming to physically teach these machines so many actions across different settings. “One natural idea is to use simulation as a training ground.
While there has been significant progress over the last few years in the physics engines that power robotics simulators, one of the remaining challenges has been creating sufficiently rich and diverse simulation content to capture the complexity of the real world,” says Russ Tedrake, the Toyota Professor of Electrical Engineering and Computer Science (EECS), Aeronautics and Astronautics, and Mechanical Engineering at MIT, and a principal investigator at MIT’s Computer Science and Artificial Intelligence Laboratory (CSAIL).
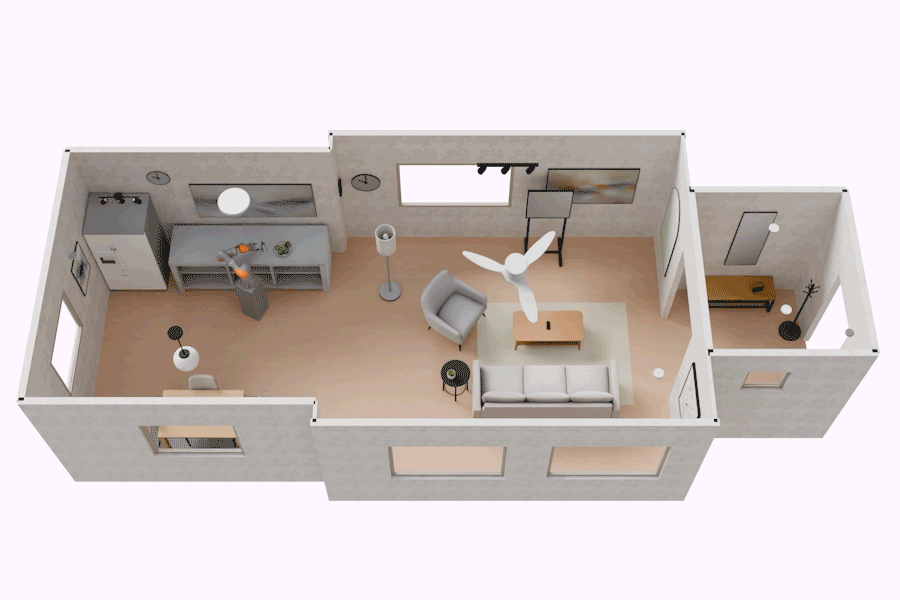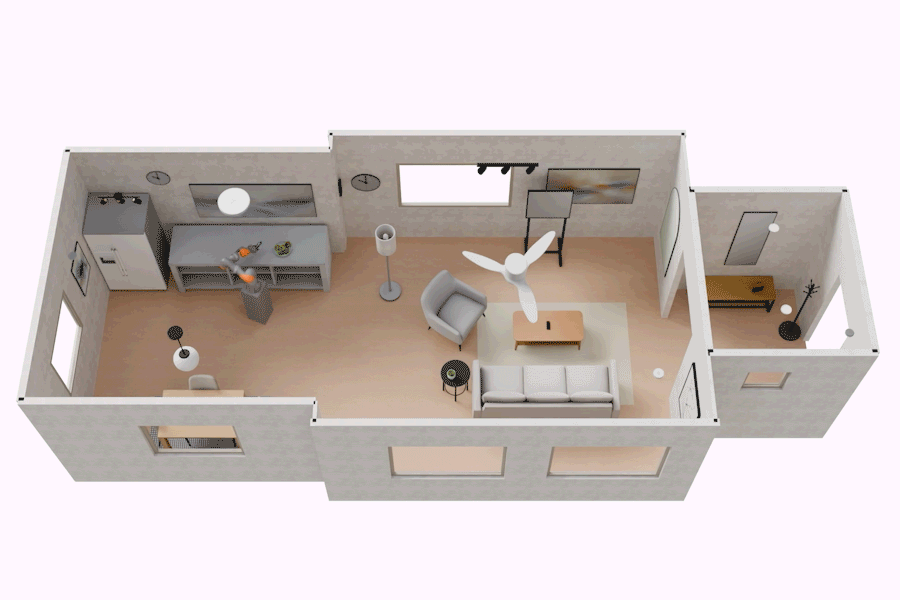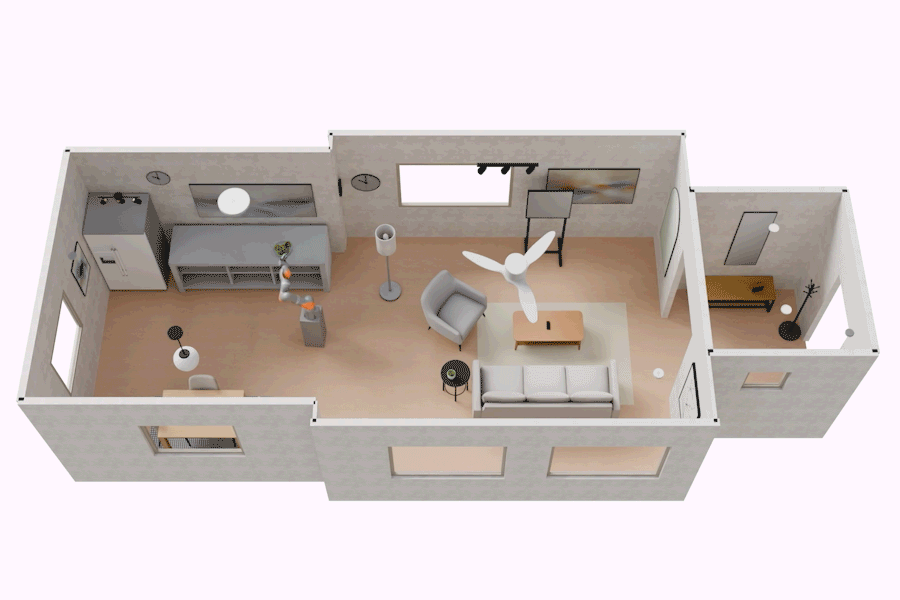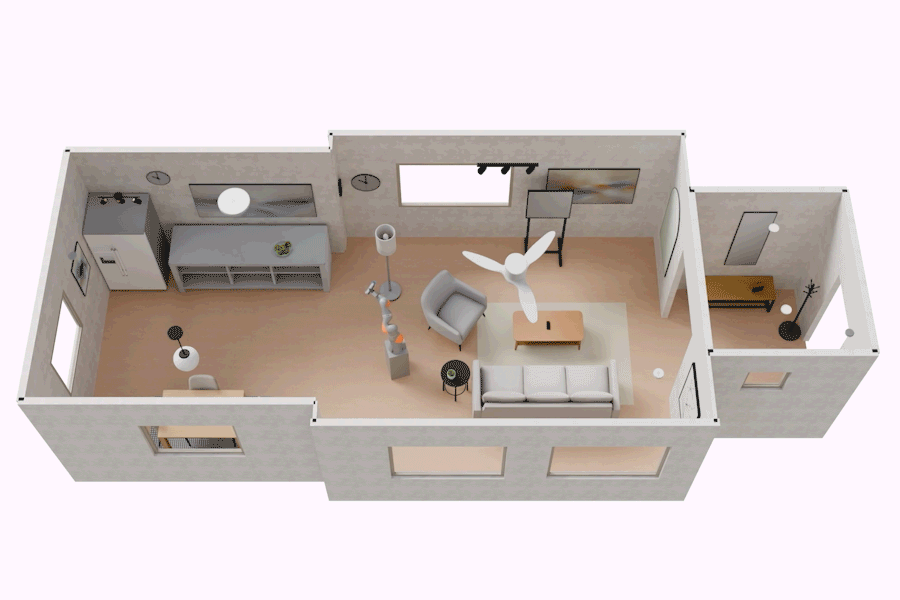
It turns out that AI agents, or semi-autonomous programs that “think” and complete well-defined tasks, could help produce the lifelike virtual settings that robots need. The new “SceneSmith” system developed by researchers at MIT CSAIL and Toyota Research Institute uses three agents to piece together the objects, walls, and overall look of a 3D scene.
Its recreations of indoor spaces such as restaurants, bedrooms, and hotels are more realistic and detailed than prior systems, helping robots practice skills and try out different ways of doing tasks before they’re powered on. In turn, engineers save time on real-world testing.The agents have a sense of how everyday places are supposed to look because they each call on a multi-modal system called a vision-language model (VLM), specifically the state-of-the-art VLM GPT-5.2.
It’s trained on lots of text and images from the internet to handle more visual prompts. This advanced model gives each agent a sort of spatial knowledge: First, a “designer” agent generates the elements of a scene, then a “critic” advises whether it looks realistic, and finally, an “orchestrator” manages their back-and-forth, deciding when the design is done.
Once the three VLMs wrap up their creative collaboration, the scene is ready to load directly into physics simulation software.
“We’ve found that the system can construct 3D scenes the way a human designer would,” says MIT EECS PhD student Nicholas Pfaff, a CSAIL researcher and a lead author on a paper with Tedrake presenting the work. “We made over 1,300 scenes using a leading VLM that has internet-scale priors, and it made insanely creative and diverse arrangements.
I hadn’t taught the system to do that
Source
MIT News · 13 Jul 2026 · 20:50 CEST
Open the original at MIT News ↗