OZZZER · AI NEWS

Latest AI news.
Editorial picks.
AI News

Selected signals with a direct route back to each original source.

Share AI News
LinkedInX

Latest stories

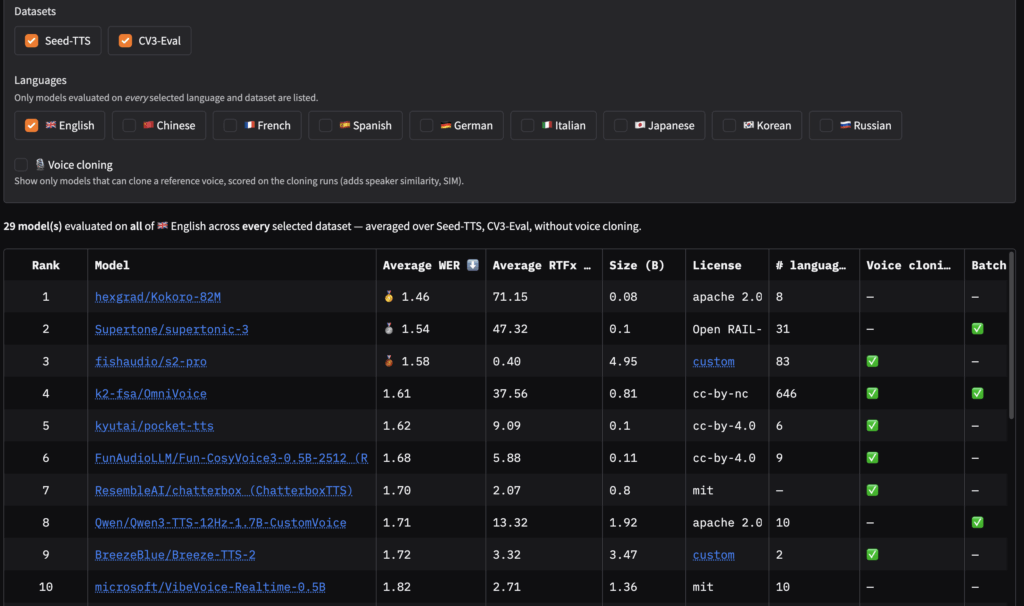
Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning

AI Audio

Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning

Publisher preview

Evaluation, however, hasn't kept pace: it remains fragmented and unstandardized. The gold standard is human preference scores such as MOS or MUSHRA (more on metrics). To this end, several arena-based leaderboards have established themselves as useful reference points for the community: These arenas compare models by presenting users with TTS outputs from two models, and asking them to choose one over the other. After collecting a sufficient number of votes, an Elo score is computed to rank models, typically with the Bradley–Terry model (see Voice Arena methodology). While human preference…

Hugging Face · 30 Sep 2026 · 02:00 CESTRead story →Original ↗
Share
LinkedInX
OpenAI gives Codex reusable cloud environments that work across devices

AI Audio

OpenAI gives Codex reusable cloud environments that work across devices

Publisher preview

OpenAI introduced new capabilities for its software engineering agent Codex, making it more useful beyond a developer’s laptop with reusable cloud development environments that can be accessed from any device. The update, announced at OpenAI’s Dev Day on Tuesday, is one of several for Codex. OpenAI also announced a refreshed Codex CLI, a new code review experience, tools to harden infrastructure, and other API enhancements. While Codex could already spin up cloud tasks to do work remotely, today’s announcement shows that OpenAI is making those cloud environments more persistent and…

TechCrunch AI · 29 Sep 2026 · 19:15 CESTRead story →Original ↗
Share
LinkedInX
Build real-time voice applications with vLLM-Omni on SageMaker AI – Part 1

AI Audio

Build real-time voice applications with vLLM-Omni on SageMaker AI – Part 1

Publisher preview

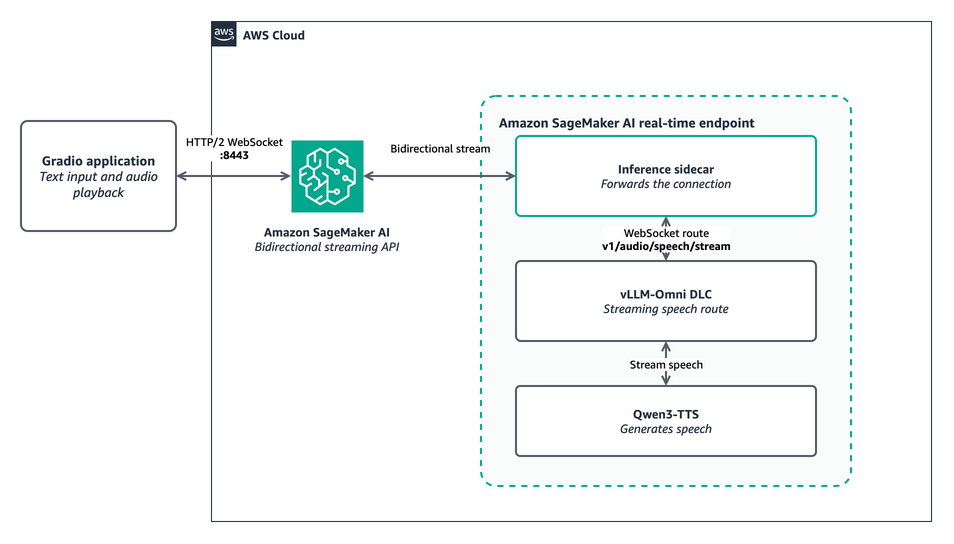
Voice agents, interactive learning applications, accessibility tools, and customer service assistants need to respond without long silent pauses. In this tutorial, you deploy a text-to-speech (TTS) model on Amazon SageMaker AI that can start playing speech before it finishes generating the full response. You use the AWS vLLM-Omni Deep Learning Container (DLC) to deploy Qwen3-TTS, stream text in and audio out over one persistent bidirectional connection, and try the workflow through a Gradio application. AWS Deep Learning Containers provide Docker images with deep learning frameworks and dependencies for training and…

AWS AI · 28 Sep 2026 · 18:15 CESTRead story →Original ↗
Share
LinkedInX
After a deepfake voice fooled her grandfather, this founder sprang into action

AI Audio

After a deepfake voice fooled her grandfather, this founder sprang into action

Publisher preview

When the call came, Tarini Padmanabhuni’s grandfather believed he was talking to his brother. The voice on the other end of the line said he’d been kidnapped and that the only way to get him back was to pay a ransom. Her grandfather paid, only to learn later that his brother had been somewhere else entirely, with no clue any of it was happening. The voice, it turned out, was a deepfake, an AI-generated imitation. “What stayed with me wasn’t the money,” Padmanabhuni says of the incident. “It was that…

TechCrunch AI · 28 Sep 2026 · 17:00 CESTRead story →Original ↗
Share
LinkedInX
Modulate raises $25M for its voice models and analysis suite

AI Audio

Modulate raises $25M for its voice models and analysis suite

Publisher preview

Boston-based voice intelligence startup Modulate has raised $25 in new funding for its platform that uses an array of small models to offer enterprises transcription, emotional analysis, deepfake and AI music detection, and policy enforcement for voice agents in regulated industries. The funding follows a popular trend among investors in the growing voice AI industry: backing companies that are trying to make AI voices sound more human. It also rivals other companies trying to detect the intent behind human conversation by analyzing it, and those trying to protect people and…

TechCrunch AI · 28 Sep 2026 · 16:05 CESTRead story →Original ↗
Share
LinkedInX
Engram is a sampler that turns broken AI hallucinations into music

AI Audio

Engram is a sampler that turns broken AI hallucinations into music

Publisher preview

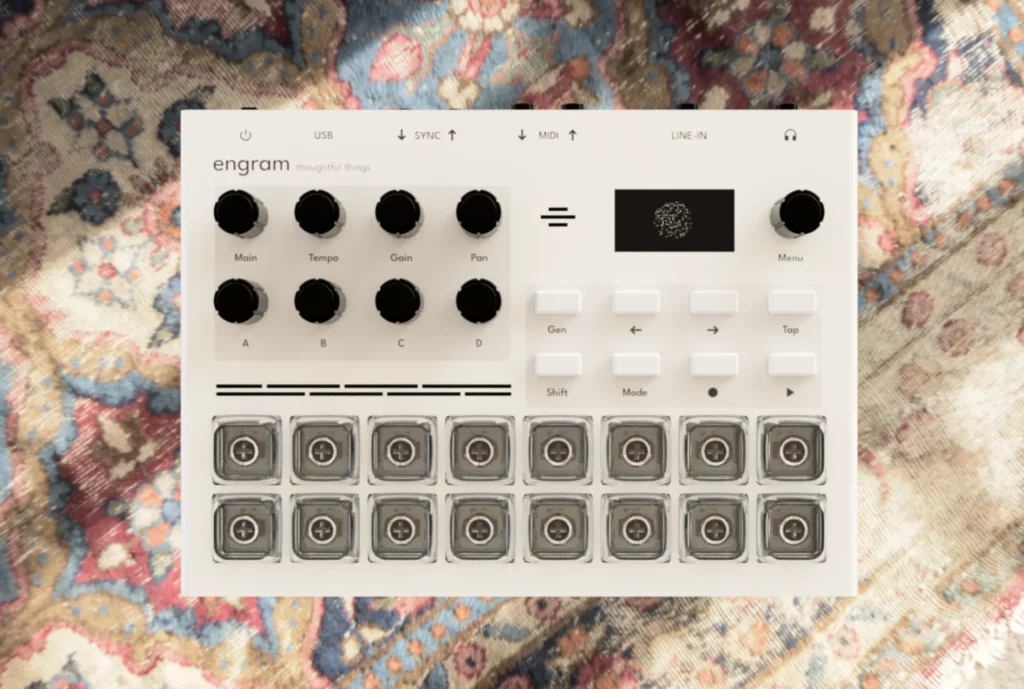
Thoughtful Things says Engram is a ‘field recorder for latent space’ and circuit-bending tiny AI models. Thoughtful Things says Engram is a ‘field recorder for latent space’ and circuit-bending tiny AI models. Music startup Thoughtful Things has just launched the Kickstarter campaign for its first instrument, Engram. It’s a sampler and groovebox that uses AI to mangle incoming audio and even hallucinate completely new sounds. This isn’t Suno in a box, though. This isn’t a “push-button, get-song” device, aimed at creating something that sounds ready for top-40 radio. It’s about…

The Verge AI · 27 Sep 2026 · 22:46 CESTRead story →Original ↗
Share
LinkedInX
Deploying real-time personalized speech with Qwen3-TTS on Amazon SageMaker AI

AI Audio

Deploying real-time personalized speech with Qwen3-TTS on Amazon SageMaker AI

Publisher preview

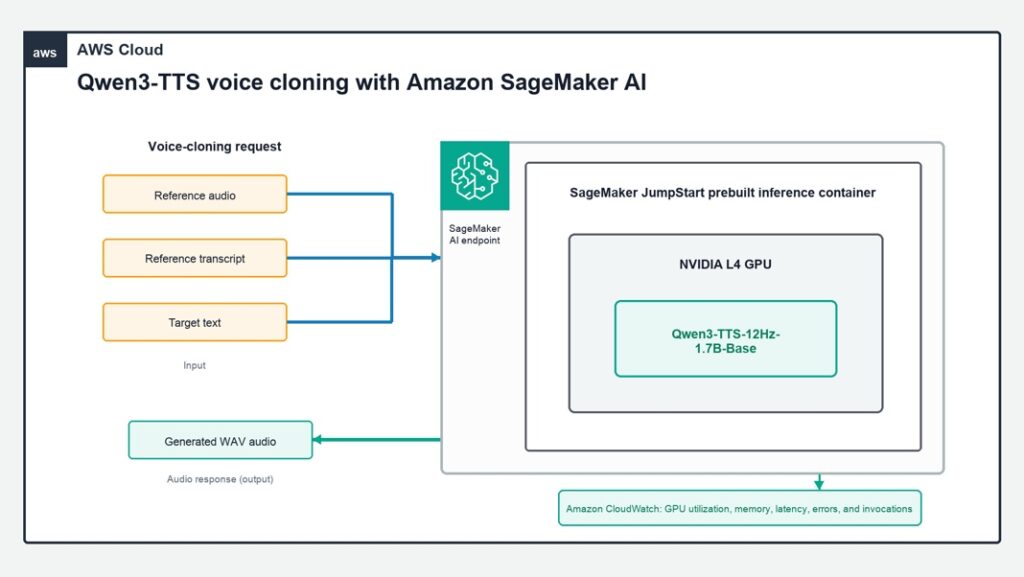
With voice cloning, you can generate new speech in a target speaker’s voice from a short reference recording, without retraining a model. You can now deploy the publicly available Qwen3-TTS-12Hz-1.7B-Base text-to-speech model from Amazon SageMaker JumpStart to a fully managed, real-time inference endpoint. Voice cloning reproduces the vocal identity of a specific speaker. Start with a short recording of the speaker and its transcript. Then supply the new text to synthesize. The model speaks that text in the reference speaker’s voice, without retraining. Media teams, educators, and application developers can…

AWS AI · 25 Sep 2026 · 18:09 CESTRead story →Original ↗
Share
LinkedInX
The Biggest News From Connect 2026

AI Audio

The Biggest News From Connect 2026

Publisher preview

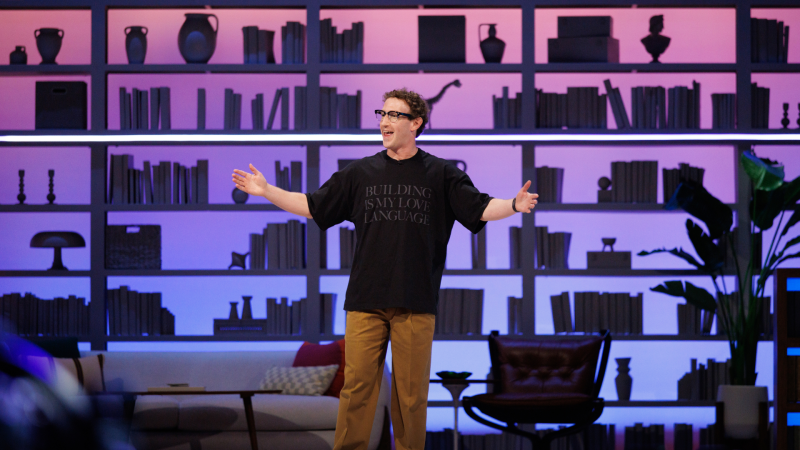
We’re building personal AI agents for everyone and a whole family of devices that let you connect with them from anywhere. We launched Muse, a first-of-a-kind personal AI agent that proactively helps you meet your goals, earlier this month. At Connect, we announced we’re bringing Muse to our AI glasses in the coming months, so you’ll soon have easy access to your personal agent wherever you go. Mark Zuckerberg showed how Muse keeps getting better with new features, connectors, and a state-of-the-art model that brings your Muse to life. Muse…

Meta AI · 24 Sep 2026 · 23:15 CESTRead story →Original ↗
Share
LinkedInX
Gemini 3.8 text-to-speech says hello

AI Audio

Gemini 3.8 text-to-speech says hello

Publisher preview

Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS are our most expressive audio generation models yet. Generate custom character voices and direct scene dialogue across Google AI Studio, Gemini API, Gemini Enterprise, Gemini Notebook, and Google Vids. Google just launched new AI tools that let you create and customize realistic voices from scratch. You can direct these voices to sound exactly how you want, from their accent to their emotional tone. It’s perfect for making audiobooks, games, or podcasts that sound like real people talking. Plus, they added safety…

Google DeepMind · 23 Sep 2026 · 17:25 CESTRead story →Original ↗
Share
LinkedInX
New Features for Meta Ray-Ban Display

AI Audio

New Features for Meta Ray-Ban Display

Publisher preview

Today at Connect 2026, we shared updates to Meta Ray-Ban Display, including new features, online ordering, and an expansion into five new markets. Navigate Hands-Free Heads-up navigation is a feature consumers consistently tell us they love in our Meta Ray-Ban Display glasses, and we’re excited to build on that. Cycling and public transit directions. Use your voice to ask for directions and your glasses will show you turn-by-turn cycling directions or real-time transit departures on the display so you can keep your phone in your pocket. Available starting later this…

Meta AI · 23 Sep 2026 · 13:53 CESTRead story →Original ↗
Share
LinkedInX
Introducing Ray-Ban Meta Audio and More AI Glasses Styles

AI Audio

Introducing Ray-Ban Meta Audio and More AI Glasses Styles

Publisher preview

Today at Connect, we announced Ray-Ban Meta Audio, our first-ever audio glasses, and our biggest expansion of AI glasses yet through our partnership with EssilorLuxottica. We’re building AI glasses for everyone. By the end of the year, we’ll offer more than 100 different glasses options across Ray-Ban, Oakley, and Meta Glasses, including lightweight frames made for all-day wear and new styles with slimmer designs and longer battery life. And with regular software updates, new AI features, and our growing ecosystem of apps and experiences, these glasses will only keep getting…

Meta AI · 23 Sep 2026 · 13:36 CESTRead story →Original ↗
Share
LinkedInX
How we built a realtime system for responsive voice AI in six months

AI Audio

How we built a realtime system for responsive voice AI in six months

Publisher preview

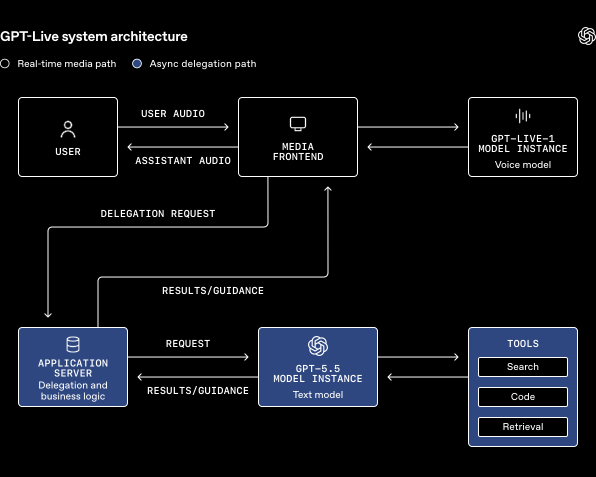
For voice AI, knowing when to speak is harder than it sounds. Human speakers effortlessly hand off to each other in a fraction of a second, but previous voice AI systems couldn’t keep up with this rhythm. Their turn-based architecture relied on tiny models known as turn detectors, which faced an unenviable task: guess too soon, and the user gets cut off; guess too late, and the response feels sluggish. Only after the detector made its decision could the much larger LLM get to work. GPT‑Live⁠, our third-generation voice system,…

OpenAI · 3 Aug 2026 · 09:00 CESTRead story →Original ↗
Share
LinkedInX