OZZZER · AI NEWS

Latest AI news.
Editorial picks.
AI News

Selected signals with a direct route back to each original source.

Share AI News
LinkedInX

Latest stories

Introducing Gemini 3.8 Live with Live Avatar

AI

Introducing Gemini 3.8 Live with Live Avatar

Publisher preview

Gemini 3.8 Live with Live Avatar brings real-time visual presence to Gemini’s conversational AI. By natively coupling our live dialogue capabilities with low-latency streaming video, Live Avatar enables a more natural and intuitive conversational experience for enterprises and their users. Building on the momentum of last week's Gemini 3.8 Live launch, today we are excited to introduce Gemini 3.8 Live with Live Avatar — bringing near real-time visual presence to our native live dialogue models. By pairing near real-time video generation with speech, the Live Avatar feature creates an experience…

Google DeepMind · 24 Sep 2026 · 18:20 CESTRead story →Original ↗
Share
LinkedInX
Advancing Private AI Compute with secure, server-side memory

AI

Advancing Private AI Compute with secure, server-side memory

Publisher preview

A technical update on our Private AI Compute architecture, which will enable persistent, cross-device AI memory with on-device privacy standards. AI is becoming more capable and intuitive — remembering what matters, understanding the world around you, and acting at your direction. Privacy and trust are core to making that possible, ensuring your data stays private and protected as AI systems evolve to provide more continuous assistance across your devices. Today, we are sharing how we will bring private, server-side memory to our Private AI Compute platform. This breakthrough resolves a…

Google DeepMind · 23 Sep 2026 · 18:00 CESTRead story →Original ↗
Share
LinkedInX
Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking

AI

Introducing Gemini 3.8 Live and 3.8 Live Extended Thinking

Publisher preview

Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking are our most advanced live dialogue models yet. Major upgrades in intelligence and parallel reasoning make them more intuitive to collaborate with and use to execute complex tasks using your voice. We are launching Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking to make voice interactions more natural, fluid, and intelligent. These models handle complex reasoning, real-time visual context, and background task execution without interrupting your conversation. You can start using these features today through the Gemini API, Google Workspace,…

Google DeepMind · 15 Sep 2026 · 19:05 CESTRead story →Original ↗
Share
LinkedInX
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber

AI

Introducing Gemini 3.8 Flash and 3.8 Flash Cyber

Publisher preview

Our newest Gemini models deliver next-generation intelligence for agentic workflows and cybersecurity. Building on the momentum of 3.7 Flash from three weeks ago and marking our third Flash release in only six weeks, today we’re introducing Gemini 3.8, our best reasoning and coding model yet, at the same speed and low cost of 3.7. Gemini 3.8 introduces 2 variants: While tailored for different deployment environments, both of today's releases are powered by the same foundational intelligence, and further accelerated by long-running agentic loops designed to recursively evaluate and refine the…

Google DeepMind · 2 Sep 2026 · 18:18 CESTRead story →Original ↗
Share
LinkedInX
BenchMIRT: What are LLM benchmarks actually measuring?

AI

BenchMIRT: What are LLM benchmarks actually measuring?

Publisher preview

Today we’re introducing BenchMIRT, a new method for auditing LLM benchmarks at the level of individual prompts—the questions and tasks a model is scored on. A benchmark is usually designed to measure a particular ability, such as safety, general reasoning, or instruction following. But the individual tasks inside it may depend on more than that stated goal. Take BBQ, a benchmark designed to test whether models rely on social stereotypes. One question asks about a grandson and grandfather trying to book an Uber. It probes age bias, but also requires…

Hugging Face · 1 Sep 2026 · 23:39 CESTRead story →Original ↗
Share
LinkedInX
Introducing @huggingface/kernels: 200+ WebGPU Kernels for Local AI

AI

Introducing @huggingface/kernels: 200+ WebGPU Kernels for Local AI

Publisher preview

Today, we are releasing the first layer of that effort: @huggingface/kernels, a minimal library for loading and running optimized WebGPU kernels from the Hugging Face Hub, together with an initial collection of 207 kernels at huggingface.co/webgpu-kernels. The collection covers operations used across a wide variety of machine learning architectures and workloads. More importantly, each kernel is published as a complete, versioned package: its interface, shader templates, correctness cases, benchmark cases, and usage instructions all live together on the Hub. We are also launching Fleet, an in-browser GPU benchmarking and testing…

Hugging Face · 1 Sep 2026 · 02:00 CESTRead story →Original ↗
Share
LinkedInX
Expanding OpenAI’s presence in Brazil

AI

Expanding OpenAI’s presence in Brazil

Publisher preview

With the launch of commercial operations in Brazil, we’re deepening our long-term commitment to the country and helping turn rapid AI adoption into broad economic and social benefits. We’re excited to expand our work in Brazil with the launch of our commercial operations. Based in São Paulo, our local team will work with Brazilian businesses, developers, researchers, and public institutions to help translate the country’s rapid adoption of AI into economic growth and meaningful progress. Brazil is one of ChatGPT’s three largest markets by weekly active users. The number of…

OpenAI · 27 Aug 2026 · 05:00 CESTRead story →Original ↗
Share
LinkedInX
Jalapeño’s first results show industry-leading speed and efficiency in AI inference

AI

Jalapeño’s first results show industry-leading speed and efficiency in AI inference

Publisher preview

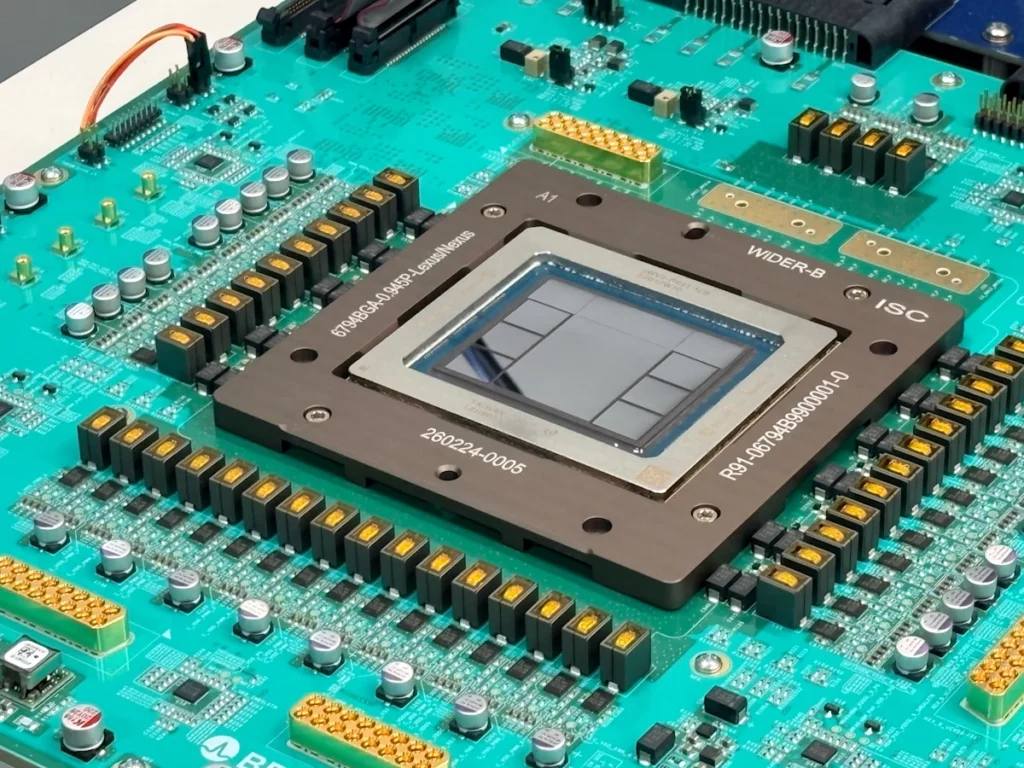
Since announcing Jalapeño, OpenAI’s first custom inference chip, we have been testing the chip and the system built around it. The results show a significant performance advance: Jalapeño can serve more AI work per unit of power while also returning responses more quickly. Jalapeño delivers both higher throughput and lower latency with one architecture, where existing hardware systems often have to make a tradeoff between the two. For customers, that can mean faster responses, more responsive agents, and more reliable access as demand grows. Our mission is to ensure that…

OpenAI · 25 Aug 2026 · 09:00 CESTRead story →Original ↗
Share
LinkedInX

AI

Advancing price-performance for developers with GPT‑5.6 in Kiro

Publisher preview

The GPT‑5.6 model family is now available in Kiro, a software development agent that brings engineering rigor and quality to AI-native coding at scale. For Kiro users, the update brings OpenAI’s latest flagship model series at the time of this announcement, including Sol, Terra, and Luna, into the development workflows where teams plan, build, review, and test software. Together, these models can help developers produce higher-quality code with fewer iterations and better value per token. GPT‑5.6 delivers more useful work from every token, with stronger performance

OpenAI · 24 Aug 2026 · 14:00 CESTRead story →Original ↗
Share
LinkedInX

AI

Replit expands access to software creation with GPT-5.6 Luna

Publisher preview

Replit is introducing Free Mode, powered by GPT‑5.6 Luna, so anyone can turn ideas into working software without worrying about token costs. As models become more capable, their economics are changing just as quickly. Better price performance makes advanced intelligence practical across more products, more workflows, and more moments. For software creation, that shift is narrowing the distance between having an idea and building something that works. Replit⁠ and OpenAI have long shared a goal: making software creation accessible to anyone with an idea, regardless of technical background. Replit was…

OpenAI · 19 Aug 2026 · 09:00 CESTRead story →Original ↗
Share
LinkedInX

AI

Partnering with CodeAI to prepare the first AI generation

Publisher preview

Today’s students will be the first generation to grow up with AI as part of everyday life. For parents and educators, the question isn’t simply whether young people will use AI, but whether they will learn to critically evaluate its outputs, understand its limitations, and use it responsibly. Right now, there’s a gap between use and understanding. The vast majority of students today are already using AI, while only 16% of high school leaders say⁠ all of their students are learning the technical knowledge to understand it in the classroom.…

OpenAI · 18 Aug 2026 · 13:00 CESTRead story →Original ↗
Share
LinkedInX
How RingCentral builds AI-native work from engineering to ops

AI

How RingCentral builds AI-native work from engineering to ops

Publisher preview

With ChatGPT Work and Codex, RingCentral builds AI product features faster and centralizes operational intelligence. With nearly three decades of innovation in business communications, RingCentral has grown into a global company generating more than $2.6 billion in annual revenue, with thousands of employees worldwide. Today, the company is extending its tradition of innovation by embracing AI-native ways of working. By giving every employee room to experiment with ChatGPT Work and Codex, RingCentral has ensured that anyone at the company, regardless of engineering experience, can build transformative products and infrastructure. To…

OpenAI · 12 Aug 2026 · 02:00 CESTRead story →Original ↗
Share
LinkedInX