Governance
Accelerate multimodal RL training with SkyRL on Amazon SageMaker HyperPod
Publisher preview
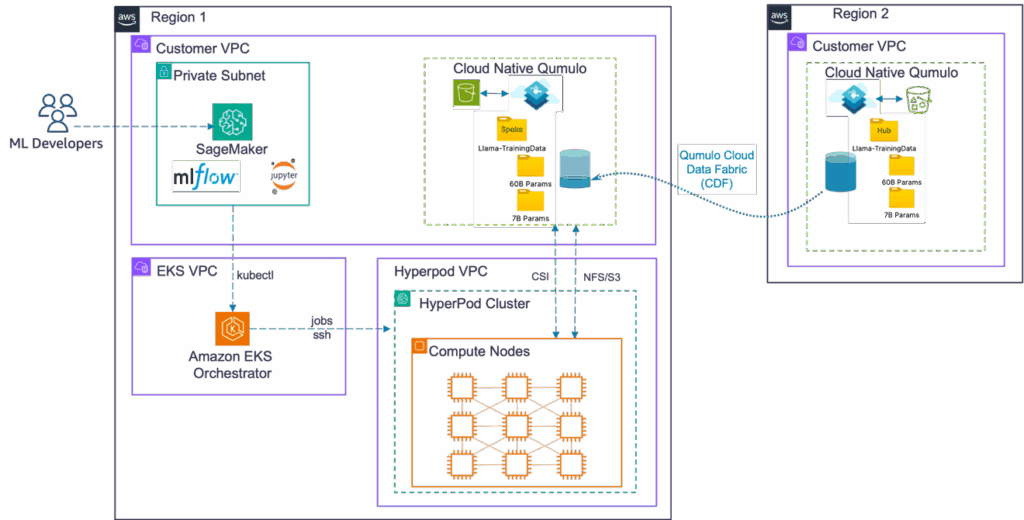
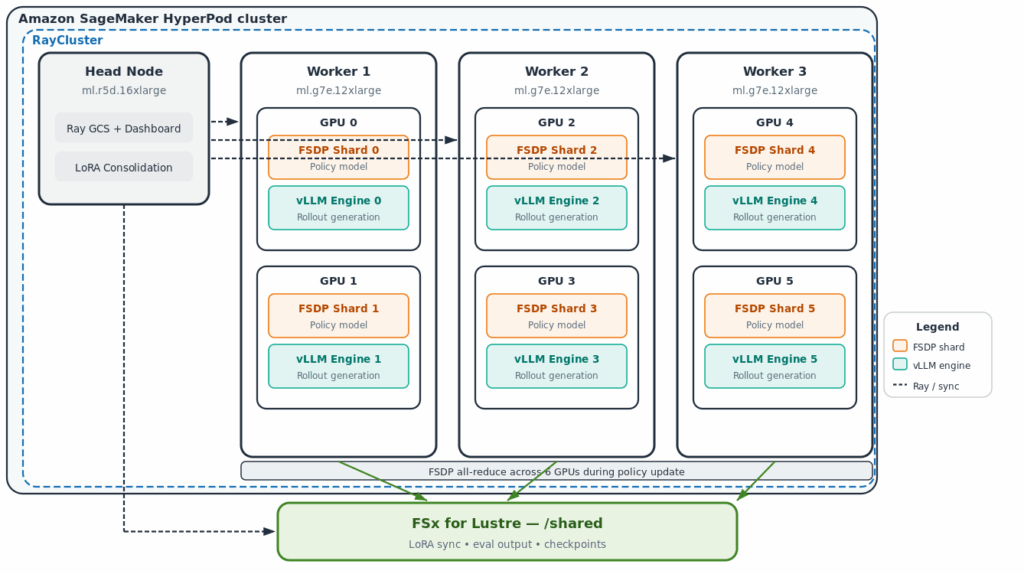
Reinforcement learning (RL) post-training is becoming a standard step in building capable language model agents. Models learn to reason and act across sequences of steps by generating trajectories, receiving rewards, and updating their policy based on outcomes. Running this at scale, across multiple nodes with hundreds of GPU-hours of rollouts per training run, requires persistent cluster infrastructure. That infrastructure needs to sustain long jobs, recover from hardware failures without losing progress, and provide visibility into training dynamics as they unfold. Amazon SageMaker HyperPod provides this infrastructure for large-scale machine learning…
AWS AI · 25 Sep 2026 · 18:18 CESTRead story →Original ↗